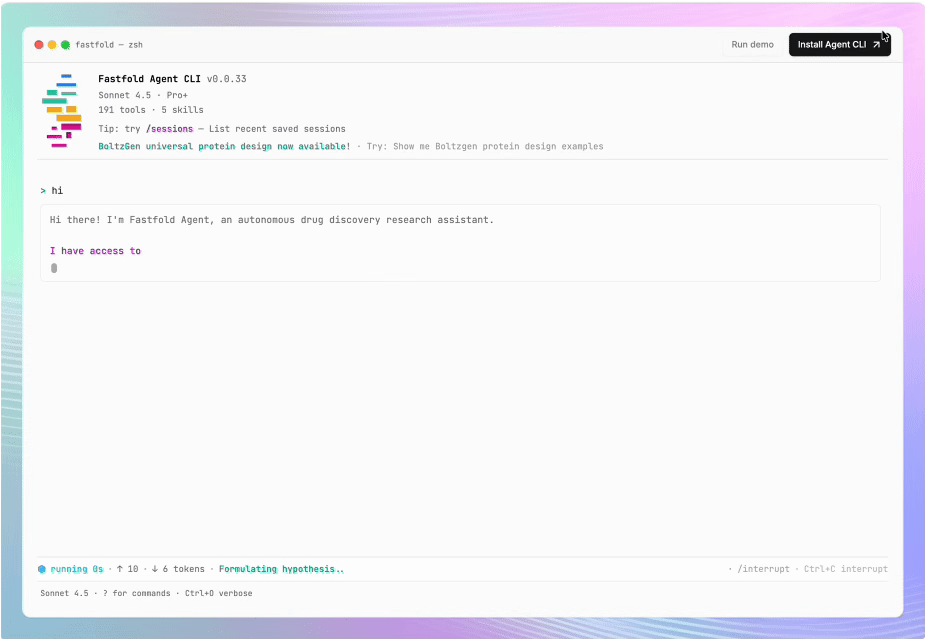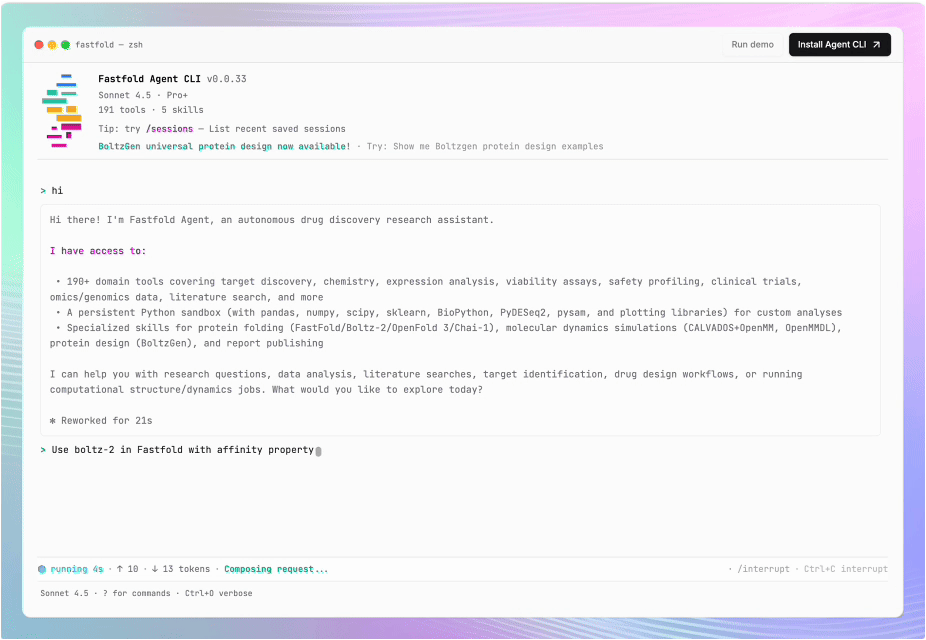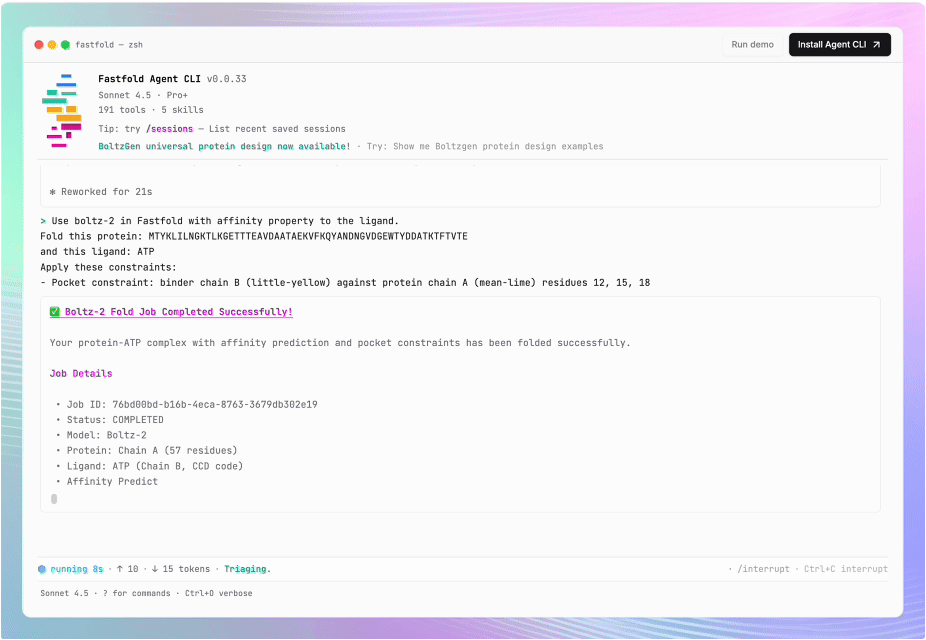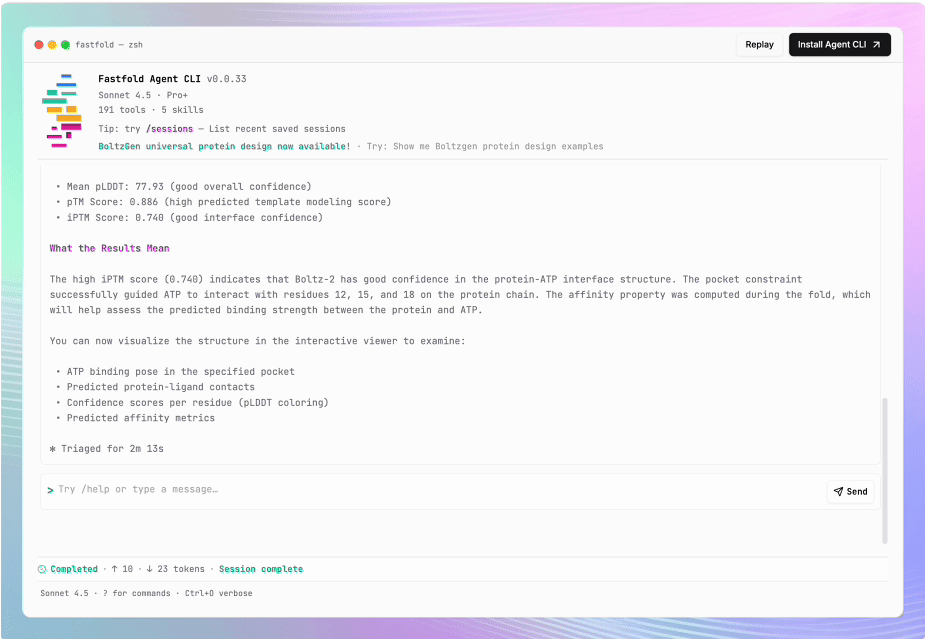
The Agent CLI (`fastfold`) is an autonomous research agent for drug discovery.
Ask questions in natural language — it plans the analysis, selects the right tools, executes them,
validates results, and returns data-backed conclusions.
Integrates with Fastfold AI Cloud for GPU compute, protein folding, and workflow orchestration.
* **PyPI:** [`fastfold-agent-cli`](https://pypi.org/project/fastfold-agent-cli/)
* **GitHub:** [fastfold-ai/fastfold-agent-cli](https://github.com/fastfold-ai/fastfold-agent-cli)
***
## Installation
Requires **Python 3.10 or later**.
Install **[uv](https://docs.astral.sh/uv/getting-started/installation/)** first (tabs per OS below), then **install Agent CLI (`fastfold`)**.
**Recommended — full `[all]` on Windows:** use **WSL2** with **Ubuntu** (official guide: **[Install WSL — Microsoft Docs](https://learn.microsoft.com/en-us/windows/wsl/install)**). In your **Ubuntu** shell, install **`uv`**, then **`uv tool install "fastfold-agent-cli[all]" --python 3.10`**.
**Native Windows (cmd/PowerShell):** **`tiledbsoma`** lacks usable wheels—prefer WSL above. If you must stay native, install **`[win_build]`** (or **`[chemistry,biology,ml,analysis]`**) instead of **`[all]`**; see tabs below.
After installing **`uv`**, restart the terminal when the installer says to, so **`PATH`** includes **`uv`**.
Official **uv** installers and package managers: **[Installing uv](https://docs.astral.sh/uv/getting-started/installation/)**.
### Install `uv`
Skip this section if **`uv`** is already on **`PATH`** (check with **`uv --version`**).
macOS
Linux
Windows (PowerShell)
Windows (WinGet)
```bash
curl -LsSf https://astral.sh/uv/install.sh | sh
```
```bash
curl -LsSf https://astral.sh/uv/install.sh | sh
```
```powershell
powershell -ExecutionPolicy ByPass -c "irm https://astral.sh/uv/install.ps1 | iex"
```
```powershell
winget install --id=astral-sh.uv -e
```
**macOS** alternative: **`brew install uv`** (see Astral docs for **`uv self update`**).
Reopen your terminal after install, then **`uv --version`**.
### Install Agent CLI (`fastfold`)
On **native Windows**, if **`[all]`** fails on **`tiledbsoma`**, use **WSL2 + Ubuntu**: **[Install WSL](https://learn.microsoft.com/en-us/windows/wsl/install)**. If you must stay on native Windows cmd/PowerShell, use **`uv ([win_build])`** (**CLI ≥ `0.0.35`** on PyPI)—or **`[chemistry,biology,ml,analysis]`** (any recent release).
uv ([all])
uv ([win_build])
pip ([all])
```bash
uv tool install "fastfold-agent-cli[all]" --python 3.10
```
```bash
uv tool install "fastfold-agent-cli[win_build]" --python 3.10
```
```bash
pip install "fastfold-agent-cli[all]"
```
Equivalent to **`win_build`** (multiple extras — always supported):
`uv tool install "fastfold-agent-cli[chemistry,biology,ml,analysis]" --python 3.10`
### Upgrade
To upgrade an existing Agent CLI install with `uv` (**match the extras your install uses**):
extras [all]
extras [win_build]
extras [compound]
```bash
uv tool install "fastfold-agent-cli[all]" --python 3.10 --upgrade
```
```bash
uv tool install "fastfold-agent-cli[win_build]" --python 3.10 --upgrade
```
```bash
uv tool install "fastfold-agent-cli[chemistry,biology,ml,analysis]" --python 3.10 --upgrade
```
If you see `Python>=3.10` not satisfied, your system Python is too old. Run `uv python install 3.10` first, then retry the install command above.
## Authentication
Interactive setup (recommended)
Environment variables
Non-interactive / CI
```bash
fastfold setup
```
```bash
export ANTHROPIC_API_KEY="sk-ant-..."
export OPENAI_API_KEY="sk-..."
export FASTFOLD_API_KEY="sk-..."
export BOLTZ_API_KEY="sk_bc_..."
```
```bash
fastfold setup --api-key sk-ant-... --fastfold-api-key sk-...
fastfold setup --provider anthropic --api-key sk-ant-... --fastfold-api-key sk-... --boltz-api-key sk_bc_...
```
Provider/model config keys:
```bash
fastfold config set llm.provider anthropic
fastfold config set llm.model claude-sonnet-4-5-20250929
fastfold config set llm.anthropic_api_key sk-ant-...
fastfold config set llm.provider openai
fastfold config set llm.model gpt-5.5
fastfold config set llm.openai_api_key sk-...
```
Notes:
* `llm.api_key` remains a legacy Anthropic-only fallback for backward compatibility.
* `fastfold setup` supports selecting providers interactively (Anthropic, OpenAI, or an OpenAI-compatible endpoint).
### Provider integrations (`/keys`)
Use `/keys` in interactive mode (or `fastfold keys` in shell mode) to review integration status and setup links.
| Service | Env var | Config key | Unlocks | Get key / setup |
| ----------------- | --------------------------- | --------------------------------------------- | --------------------------------------------- | ---------------------------------------------------------------------------------- |
| Anthropic | `ANTHROPIC_API_KEY` | `llm.anthropic_api_key` | Claude model access (default provider) | [console.anthropic.com/settings/keys](https://console.anthropic.com/settings/keys) |
| OpenAI | `OPENAI_API_KEY` | `llm.openai_api_key` | OpenAI model access | [platform.openai.com/api-keys](https://platform.openai.com/api-keys) |
| OpenAI-compatible | `OPENAI_COMPATIBLE_API_KEY` | `llm.openai_compatible_api_key` / profile key | Local/self-hosted OpenAI-compatible endpoints | [Ollama API docs](https://docs.ollama.com/api/introduction) |
| Fastfold AI Cloud | `FASTFOLD_API_KEY` | `api.fastfold_cloud_key` | Fastfold cloud skills and integrations | [cloud.fastfold.ai/api-keys](https://cloud.fastfold.ai/api-keys) |
| Boltz | `BOLTZ_API_KEY` | `api.boltz_api_key` | Boltz API skills (`boltz` skill modes) | [api.boltz.bio/console](https://api.boltz.bio/console) |
| IBM RXN | `IBM_RXN_API_KEY` | `api.ibm_rxn_key` | Retrosynthesis workflows | [rxn.res.ibm.com](https://rxn.res.ibm.com) |
| Lens.org | `LENS_API_KEY` | `api.lens_key` | Patent search workflows | [lens.org subscriptions](https://www.lens.org/lens/user/subscriptions) |
| SendGrid | `SENDGRID_API_KEY` | `notification.sendgrid_api_key` | Email notification delivery | [sendgrid.com](https://sendgrid.com) |
| Lambda Labs | `LAMBDA_API_KEY` | `compute.lambda_api_key` | GPU compute job submission | [cloud.lambdalabs.com](https://cloud.lambdalabs.com) |
| RunPod | `RUNPOD_API_KEY` | `compute.runpod_api_key` | GPU compute job submission | [runpod.io](https://www.runpod.io) |
Boltz quick setup (interactive):
```bash
/keys set-boltz
```
This flow sets `BOLTZ_API_KEY`, then offers Boltz skill install (`fastfold-ai/skills@skills/boltz`) and `boltz-api` CLI install.
Configured tool keys are mirrored into the session environment on startup, so shell/skill subprocesses can read `BOLTZ_API_KEY` and `FASTFOLD_API_KEY` without extra export steps.
### Local & OpenAI-compatible models (Ollama, Unsloth, …)
Point the CLI at a local or self-hosted OpenAI-compatible endpoint. Use the wizard:
```bash
fastfold setup --provider openai_compatible
```
It asks for the endpoint type (Ollama / Unsloth / other), the base URL (defaults: Ollama `http://localhost:11434/v1`, Unsloth `http://localhost:8888/v1`), an API key (Ollama accepts `ollama`), then discovers and lets you pick a model. Or configure directly:
```bash
fastfold config set llm.provider openai
fastfold config set llm.openai_base_url http://localhost:11434/v1
fastfold config set llm.openai_compatible_backend ollama
fastfold config set llm.openai_compatible_api_key ollama
fastfold config set llm.model llama3.1
```
Use `/model` in interactive mode to switch between Anthropic, OpenAI, and local/open models (Gemma, Qwen, DeepSeek, …) at any time.
If a local compatible endpoint is active (for example Ollama) but a cloud-only model id is set (`gpt-*`), the CLI now auto-heals to the active profile default model to avoid model-not-found loops.
***
## Quick start
```bash
# Start interactive session
fastfold
# Single query
fastfold "What are the top degradation targets for this compound?"
# Validate your setup
fastfold doctor
```
{/* Screenshot: fastfold interactive session */}
{/* */}
***
## Example queries
### Target prioritization
```bash
fastfold "I have a CRBN molecular glue. Proteomics shows it degrades IKZF1, GSPT1,
and CK1α. Which target should I prioritize?"
```
### Protein folding
```bash
fastfold "Fold this sequence with boltz-2 and find the binding pockets: MALWMRLLPLL..."
```
{/* Screenshot: protein folding result with structure viewer link */}
{/* */}
### Combination strategy
```bash
fastfold "My lead compound is immune-cold. What combination strategy should I use?"
```
***
## Interactive mode commands
Inside `fastfold` interactive mode:
| Command | Description |
| ----------------------- | -------------------------------------------------------------------------------------------------- |
| `/help` | Command reference and examples |
| `/tools` | List all tools with status |
| `/skills` | List currently loaded skills (author, last updated, version) |
| `/skills-find [query]` | Discover installable skills from the Fastfold catalog |
| `/skills-add ` | Install a skill (GitHub URL, `owner/repo@path`, local path, or name) |
| `/skills-upgrade` | Sync the catalog and update installed skills |
| `/skills-remove ` | Remove an installed skill |
| `/model` | Switch model/provider interactively |
| `/settings` | Configure UI/agent preferences |
| `/config` | Show active runtime config |
| `/keys` | Show key setup status and masked previews (`/keys set-compatible `, `/keys set-boltz`) |
| `/new` | Start a brand-new local session (fresh UI + new session id) |
| `/tasks` | Show background task watcher status (`/tasks refresh` for live probe) |
| `/interrupt` | Interrupt active generation (`/interrupt!` or `/interrupt --force` to force stop) |
| `/agents N ` | Run N parallel research agents |
| `/sessions`, `/resume` | Session lifecycle (`/sessions delete ` supported) |
| `/copy`, `/export` | Copy or export current session output |
| `/notebook` | Export current session as Jupyter notebook |
| `/export-share` | Export the current session, post to Slack, and save to library |
| `/compact` | Compress context for longer runs |
| `/plan` | Toggle plan-preview mode |
| `/upgrade` | Upgrade installed CLI via `uv tool install ... --upgrade` |
| `/clear`, `/exit` | Clear terminal or exit session |
| `/usage` | Token and cost tracking |
During an active generation:
* `/interrupt` requests a graceful stop
* `Ctrl+C` once does the same interrupt request
* `Ctrl+C` again quickly (or `/interrupt!`) force-stops the current run
{/* Screenshot: interactive mode with /tools output */}
{/* */}
***
## Local sessions and persistence
Agent CLI persists interactive session history locally by default. You can close and reopen the CLI, then continue prior work with `/sessions`, `/resume`, `fastfold --resume `, or `fastfold --continue`.
What is persisted per session:
* turn history (query/answer trajectory)
* tool/reasoning trace replay data for richer resume rendering
* per-turn usage totals used by `/usage`
* extracted durable IDs (for example job/workflow UUIDs) for follow-up context
Key local paths:
* config: `~/.fastfold-cli/config.json` (backup: `~/.fastfold-cli/config.json.bak`)
* interactive prompt history: `~/.fastfold-cli/history`
* sessions: `~/.fastfold-cli/sessions/.jsonl`
* trace events: `~/.fastfold-cli/sessions/.trace.jsonl`
Session lifecycle commands:
```bash
/sessions
/resume
/sessions delete
/new
fastfold --resume
fastfold --continue
```
***
## Upgrade command
You can upgrade in-place from inside the interactive UI with `/upgrade`, or from shell:
macOS / Linux default
Windows native default
```bash
uv tool install "fastfold-agent-cli[all]" --python 3.10 --upgrade
```
```bash
uv tool install "fastfold-agent-cli[win_build]" --python 3.10 --upgrade
```
The CLI checks PyPI on startup and shows an upgrade hint when a newer version is available.
***
## Background task workflow
Use background tasks for long-running waits and keep working in the same session.
```text
Can you run the BoltzGen `vanilla_target_binding_site` example with one target and one design budget, then keep the wait step in the background so we can continue? Please share the `workflow_id` and output file path.
```
Then monitor watcher state from the prompt:
```bash
/tasks
/tasks refresh
```
If you're using Warp Terminal, completed background tasks can also trigger desktop notifications (when Warp notifications are enabled in your OS and Warp settings). See [Warp Desktop Notifications](https://docs.warp.dev/terminal/more-features/notifications/).
You can tune how long the watcher keeps listening for background tasks:
```bash
fastfold config set agent.background_watch_timeout_s 10800
```
Recommended pattern for job/workflow skills (fold, BoltzGen, MD):
* run submit/create steps in foreground and return `job_id`/`workflow_id` immediately
* run only long wait/log-watch steps in background
* use `/tasks` to verify watcher status while you continue other queries
***
## Tool categories
| Category | Examples |
| -------------- | -------------------------------------------------------------------------------------------- |
| **Target** | Neosubstrate scoring, degron prediction, co-essentiality networks |
| **Chemistry** | SAR analysis, fingerprint similarity, scaffold clustering |
| **Expression** | L1000 signatures, pathway enrichment, TF activity, immune scoring |
| **Viability** | Dose-response modeling, PRISM screening, therapeutic windows |
| **Structure** | AlphaFold fetch, docking, binding sites, MD simulation |
| **Folding** | Fastfold AI Cloud: boltz-2, openfold3, chai1, intellifold, monomer, multimer, simplefold\_\* |
| **Literature** | PubMed, OpenAlex, ChEMBL search |
| **DNA** | ORF finding, codon optimization, primer design |
```bash
fastfold tool list # see all 190+ tools
fastfold skills list # see loaded skills
```
***
## Skills
Skills are packaged instructions + scripts (folding, MD, protein design, reporting) that the agent runs on demand. Only two helper skills (`find-skills`, `skill-creator`) ship bundled; the rest are installed from the [Fastfold catalog](https://github.com/fastfold-ai/skills) and other sources, so they grow over time.
### Manage from the CLI
```bash
fastfold skills list # installed + bundled skills
fastfold skills find [query] # discover from the Fastfold catalog
fastfold skills add fastfold-ai/skills@skills/fold # install one skill
fastfold skills add fastfold-ai/skills # install all Fastfold skills
fastfold skills info fold # show details
fastfold skills upgrade # sync catalog + update installed
fastfold skills remove fold # remove one skill
fastfold skills delete --all # remove ALL user-installed skills (asks to confirm)
```
Inside an interactive session, use `/skills`, `/skills-find`, `/skills-add`, `/skills-upgrade`, and `/skills-remove`. The agent can also discover/install skills itself when you enable `fastfold config set skills.allow_agent_install true`.
### Versioning and updates
The Fastfold catalog ships GitHub Releases (one semver tag per catalog version). `fastfold skills list` (and `/skills`) show **Author**, **Updated**, and **Version** — the version is the catalog's latest release tag (e.g. `v1.0.0`) and the author is the source repo org (e.g. `fastfold-ai`); sources without a release show `Version not available`. Run `fastfold skills upgrade` (or `/skills-upgrade`) to update. On launch, a non-blocking notice appears when a newer release exists (`Skills update available: v1.0.0 -> v1.1.0 Run /skills-upgrade`); the check is cached locally and refreshed in the background so startup stays fast.
### Install during setup
`fastfold setup` offers a skills step: it live-fetches the Fastfold catalog, lets you multi-select (all preselected), suggests community collections, and accepts custom sources. Non-interactive: `fastfold setup --skills "fastfold-ai/skills@skills/fold,..."` or `--skip-skills`.
### Install method and location
* When **Node/`npx`** is available, installs prefer `npx skills add` into a Fastfold-owned dir (`~/.fastfold-cli/.claude/skills`).
* Otherwise a native **`git clone`** installs into `~/.fastfold-cli/skills`.
* Both locations are discovered automatically from any directory.
### Community skill collections
Install skills from other providers (each command installs the whole collection):
```bash
fastfold skills add K-Dense-AI/scientific-agent-skills # K-Dense-AI
fastfold skills add anthropics/life-sciences # Anthropic
fastfold skills add google-deepmind/science-skills # DeepMind
```
Create your own with the bundled `skill-creator` skill. See the [Skills guide](/agents/skills) for the catalog details and per-skill references.
***
## Data management
```bash
fastfold data pull depmap # DepMap CRISPR, mutations, expression
fastfold data pull prism # PRISM cell viability
fastfold data pull msigdb # Gene sets
# Or point to existing data
fastfold config set data.depmap /path/to/depmap/
```
***
## Reports
```bash
fastfold report list # list saved reports
fastfold report publish # convert latest .md to .html
fastfold report show # open in browser
```
### Share to Slack from interactive mode
If you connected Slack in Fastfold Cloud and configured the `agent_cli_report` channel, you can share the current session report directly:
```bash
/export-share
```
What it does:
* exports your current session to markdown
* sends it to your configured Slack report channel
* saves a copy to your library
* adds a "View in Library" link in Slack when available
{/* Screenshot: exported HTML report */}
{/* */}
***
## Troubleshooting
| Symptom | Fix |
| ----------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `fastfold` fails at startup | `fastfold doctor` |
| No API key error | `fastfold setup` or `export ANTHROPIC_API_KEY=...` |
| Data not found | `fastfold data pull ` |
| `tiledbsoma.dll` / `tiledbsoma` builds fail on native Windows (`[all]`) | Prefer **[WSL2 install](https://learn.microsoft.com/en-us/windows/wsl/install)** + Ubuntu + **`[all]`**. Native Windows: **`[win_build]`** (CLI ≥ **`0.0.35`**) or **`[chemistry,biology,ml,analysis]`**. |
| Missing dependency (pip fallback) | `pip install "fastfold-agent-cli[all]"` |
| Session lost | `fastfold --continue` |
***
## Next steps
* Python SDK for programmatic workflows → [SDK Install](/sdk/install)
# Introduction
This guide covers our HTTP REST endpoints alongside
streaming and realtime interfaces used to fold protein sequences,
retrieve structural properties, and orchestrate workflows and agents.
You can call the API from any environment that can make HTTPS requests,
or use our [first-class SDKs](/quick-start) for Python and JavaScript for a simpler,
typed client experience.
## Authentication
You can create an API key in the [Fastfold dashboard](https://cloud.fastfold.ai/api-keys). Once you have an API key, you can use it to authenticate requests to the API.
API key authentication is done via the `Authorization` header.
```bash
Authorization: Bearer
```
Remember to keep your API key secure, as anyone with your API key can make requests on your behalf.
Next, explore the available endpoints and how to use them.
## OpenAPI spec
For agents and tooling, you can read the raw OpenAPI YAML directly:
* [`/api/openapi.yaml`](/api/openapi.yaml)
## Webhooks
Webhook setup, enablement patterns, and delivery payload shapes are documented in:
* [Webhook Overview](/webhooks/overview)
* [Enable Webhooks](/webhooks/enable-webhooks)
* [Custom HTTP Config](/webhooks/custom-http-config)
* [Event Payloads](/webhooks/event-payloads)
## Quota Limits
All API requests are subject to quota limits. You can view your quota limits in the [Usage dashboard](https://cloud.fastfold.ai/usage).
If you exceed your quota limits, you will receive a 429 error. While on beta, you can upgrade your quota limits by contacting us at [hello@fastfold.ai](mailto:hello@fastfold.ai).
## Next steps
Now that you're authenticated and know about quota limits, you can start using the API.
# Changelog
Notable, user-facing changes across the Fastfold platform. Entries are grouped by date and tagged by
area. For complete per-project history, see the
[Agent CLI CHANGELOG](https://github.com/fastfold-ai/fastfold-agent-cli/blob/main/CHANGELOG.md) and the
[Skills CHANGELOG](https://github.com/fastfold-ai/skills/blob/main/CHANGELOG.md).
## 2026-06-23
### Agent CLI `v0.0.64`
* Added `fastfold agent fork ` to import shared cloud threads into local sessions.
* New fork flow supports:
* public-link shares without API key auth
* restricted-email shares with `FASTFOLD_API_KEY` from an allowed account
* optional `--no-files` mode to import transcript only
* Fork now prints import stats (messages/files/folders), restore location, and a `--resume` hint.
* Improved UX for long imports with phase-based loaders and friendly non-traceback errors for missing/forbidden shares.
### Cloud Platform
* Added dedicated fork UX in shared chat and authenticated chat headers:
* local CLI fork command copy
* cloud fork action
* transcript export from the fork surface
* Updated share/fork UI separation so sharing settings and forking actions are no longer mixed in one modal.
## 2026-06-22
### Skills `v1.1.0` → `v1.1.1`
* Reworked the [`boltz`](/agents/skills#boltz) skill to drive the official `boltz-api` CLI directly,
replacing the bundled runner script with a thin persistence helper.
* Runtime-aware result persistence: local agents (Agent CLI, Claude Code, Codex, Cursor) download
straight into the agent output dir, while hosted Cloud sandboxes persist to the S3-backed workspace.
* Documented [compute providers and API keys](/agents/skills#api-key-setup): `FASTFOLD_API_KEY` for the
Fastfold Cloud Jobs/Workflows API and `BOLTZ_API_KEY` for the Boltz API.
### Agent CLI `v0.0.63`
* Fixed `CERTIFICATE_VERIFY_FAILED` failures when installing skills on Windows without `npx`/`git`
(GitHub archive downloads now use `httpx` with certifi-backed TLS).
### Cloud Platform
* Virtualized the Agent IDE file tree so sessions with thousands of files stay responsive — typing
in the composer and scrolling no longer lag when the workspace is large.
* Added collapse/expand subfolders to the file tree's actions menu, plus a file and folder counter so
you can see the size of a workspace at a glance.
* Folder downloads now stream into a single zip instead of downloading each file individually, which
is faster and preserves the folder structure for large result sets.
## 2026-06-21
### Agent CLI `v0.0.58` → `v0.0.62`
* Native Boltz provider onboarding in interactive (`/keys set-boltz`) and setup flows, with optional
install of the `boltz` skill and `boltz-api` CLI plus `fastfold doctor` health checks.
* Skills install now works without `npx` or `git` via a GitHub archive fallback during setup, upgrade,
and `/skills-upgrade` catalog sync.
* `/upgrade` now runs a full skills sync automatically after the CLI package upgrade.
# Fastfold AI
Scientists and AI agents doing real science.
Fastfold provides managed structure prediction, workflow execution, file-backed pipelines, and agent integrations through one platform.
## Why use Fastfold
* **Scientists + agents**: collaborate with AI agents to plan, run, and iterate on folding experiments.
* **Managed infrastructure**: run jobs and workflows on managed compute without handling DevOps yourself.
* **Reproducibility first**: keep runs versioned and traceable so results are easy to compare and share.
* **Flexible integrations**: start with the Python SDK and CLI, drop to raw REST when you need full control, or work through agents.
## Choose your path
* **Python SDK and CLI** for notebooks, scripts, CI, payload files, YAML submit, and workflow helpers: [/sdk/install](/sdk/install)
* **Agents** for Agent CLI, skills, and PyMOL Agent: [/agents](/agents)
* **REST API** for direct HTTP integrations and endpoint reference: [/api](/api)
## Python SDK and CLI
Use the SDK when you want typed helpers for fold jobs, workflow helpers for OpenMM, OpenMMDL, and BoltzGen, plus access to raw payload workflows when needed.
```bash
pip install fastfold-ai
```
```python
from fastfold import Client
client = Client()
job = client.fold.create(
sequence="LLGDFFRKSKEKIGKEFKRIVQRIKDFLRNLVPRTES",
model="boltz-2",
is_public=True,
)
results = client.jobs.wait_for_completion(job.id, poll_interval=5.0, timeout=900.0)
print("Status:", results.job.status)
print("CIF URL:", results.cif_url())
print("Mean PLDDT:", results.metrics().mean_PLDDT)
print("Viewer:", results.get_viewer_link())
```
Use the SDK CLI (`fastfold-cli`) when you want the same platform features in shell scripts or CI:
```bash
fastfold-cli fold --sequence "LLGDFFRKSKEKIGKEFKRIVQRIKDFLRNLVPRTES" --model boltz-2
fastfold-cli jobs from-yaml --file fastfold/examples/fold/boltz2_affinity_input.yaml --model boltz-2
fastfold-cli workflows openmm from-manual-files --pdb ./protein.pdb --pae ./pae.json --simulation-name AF-P00698 --sim-length-ns 10 --box-length 50
```
The SDK section under [/sdk](/sdk) includes install, overview, SDK CLI recipes, fold jobs, OpenMM, OpenMMDL, BoltzGen, generic workflows, webhooks, and report sharing.
## Agent CLI
Use the Agent CLI when you want Fastfold to plan and run multi-step research flows from natural-language prompts.
uv (recommended)
Docker
```bash
uv tool install "fastfold-agent-cli[all]" --python 3.10
```
```bash
git clone https://github.com/fastfold-ai/fastfold-agent-cli.git
cd fastfold-agent-cli
docker compose build
```
```bash
docker compose run --rm fastfold
```
```bash
fastfold setup
fastfold "Fold this sequence with boltz-2 and show me the binding pockets: MALWMRLLPLL..."
```
Install, setup, Docker, and command reference → [Agent CLI](/agents/cli)
## Skills
If you use coding agents, install the official Fastfold skills package to expose fold and workflow operations in a reusable agent-friendly format.
Skills CLI (any agent)
Fastfold Agent CLI
```bash
npx skills add fastfold-ai/skills
```
```bash
fastfold skills add fastfold-ai/skills
fastfold skills find
```
* Skills repo: [github.com/fastfold-ai/skills](https://github.com/fastfold-ai/skills)
* Skills listing: [skills.sh/fastfold-ai/skills](https://skills.sh/fastfold-ai/skills)
* Detailed guide: [/agents/skills](/agents/skills)
## PyMOL Agent
Bring Fastfold skills directly into PyMOL with a chat-driven plugin workflow.
```bash
curl -LsSf http://fastfold.ai/pymol-agent/install.sh | sh
```
Install, setup, and usage guide → [PyMOL Agent](/agents/pymol)
## `llms.txt`
This docs site includes AI-friendly exports:
* [`/llms.txt`](/llms.txt): concise index with documentation links.
* [`/llms-full.txt`](/llms-full.txt): full combined markdown content.
You can also append `.mdx` to docs paths to retrieve markdown content for a specific page (for example, `/sdk/install.mdx`).
## Next steps
Start with the integration path that matches how you want to work:
* First SDK or CLI run: [/quick-start](/quick-start)
* Install and configure the SDK: [/sdk/install](/sdk/install)
* Browse SDK recipes by task: [/sdk](/sdk)
* Read the REST reference: [/api](/api)
# PyMOL Agent
PyMOL Agent is a PyMOL plugin that combines Fastfold skills with natural-language structure editing.
You can run fold or MD workflows, load generated artifacts into PyMOL, and iterate on visualization in one place.
* **GitHub:** [fastfold-ai/fastfold-pymol-agent](https://github.com/fastfold-ai/fastfold-pymol-agent)
* **Hosted installer:** [http://fastfold.ai/pymol-agent/install.sh](http://fastfold.ai/pymol-agent/install.sh)
***
## Quick install
```bash
curl -LsSf http://fastfold.ai/pymol-agent/install.sh | sh
```
Agent-only mode (assumes PyMOL already installed):
```bash
curl -LsSf http://fastfold.ai/pymol-agent/install.sh | sh -s -- --agent-only
```
Custom conda environment:
```bash
curl -LsSf http://fastfold.ai/pymol-agent/install.sh | sh -s -- --env-name myenv
```
***
## First run in PyMOL
After install:
```bash
conda activate myenv
pymol
```
Then in the PyMOL command area:
```text
fastfold doctor
fastfold setup anthropic
fastfold setup fastfold
fastfold ui
```
Get keys:
* Fastfold API keys: [https://cloud.fastfold.ai/api-keys](https://cloud.fastfold.ai/api-keys)
* Anthropic dashboard: [https://platform.claude.com/dashboard](https://platform.claude.com/dashboard)
***
## Example workflow
```text
Use esm1b in Fastfold to run a fold job for my sequence, wait for completion,
load the resulting structure in PyMOL, then show cartoon and color by secondary structure.
```
You can track submitted jobs in your account dashboard: [https://cloud.fastfold.ai/jobs](https://cloud.fastfold.ai/jobs).
***
## Next steps
* Full Agent CLI research workflows: [Agent CLI](/agents/cli)
* Scripted automation and API usage: [SDK Install](/sdk/install)
* Agent skills guide: [Skills](/agents/skills)
# Python SDK
Python client and CLI for Fastfold jobs, workflows, library uploads, and report sharing.
## Installation
Requires **Python 3.8+**.
PyPI
Local (project root)
Development (editable)
```bash
pip install fastfold-ai
```
```bash
pip install .
```
```bash
pip install -e .
```
## Authentication
Set your API key in the environment:
macOS / Linux
Windows
```bash
export FASTFOLD_API_KEY="sk-...your-api-key"
```
```bash
setx FASTFOLD_API_KEY "sk-...your-api-key"
```
Then create the client (it reads `FASTFOLD_API_KEY` by default):
```python
from fastfold import Client
client = Client()
```
You can also pass credentials explicitly (handy in CI or when using multiple keys):
```python
from fastfold import Client
client = Client(api_key="sk-...your-api-key")
```
## Base URL (optional)
By default, the SDK targets the Fastfold API. If you need to override it (self-hosting, proxies, or testing), set a base URL:
```python
from fastfold import Client
client = Client(base_url="https://api.fastfold.ai")
```
## Services
The current SDK exposes:
* `client.fold` for the simplest fold-job flow
* `client.jobs` for raw payload creation, YAML submit, results, polling, visibility, and render helpers
* `client.workflows` for generic workflow creation, status, task results, execution, Evolla linked-history helpers, and workflow YAML endpoints
* `client.library` for item creation and file uploads
* `client.openmm`, `client.openmmdl`, `client.evolla`, and `client.boltzgen` for common multi-step workflow flows
* `client.reports` for Slack markdown reports
## Your first fold
```python
from fastfold import Client
client = Client() # reads FASTFOLD_API_KEY
myJob = client.fold.create(
sequence="LLGDFFRKSKEKIGKEFKRIVQRIKDFLRNLVPRTES",
model="boltz-2",
is_public=True,
)
print("Job ID:", myJob.id)
results = client.jobs.wait_for_completion(myJob.id, poll_interval=5.0, timeout=900.0)
print("Status:", results.job.status)
print("CIF URL:", results.cif_url())
print("Mean PLDDT:", results.metrics().mean_PLDDT)
link = results.get_viewer_link()
print("Open in viewer:", link)
```
## Full job payloads
If you already have the full `JobInput` shape, submit it directly:
```python
import json
from pathlib import Path
from fastfold import Client
client = Client()
payload = json.loads(Path("fastfold/examples/fold/job_payload.json").read_text())
job = client.jobs.create(payload)
print(job.id)
```
## Boltz-style YAML jobs
Use this when your input file is the sequence-oriented YAML schema and you want the backend to convert it into `JobInput`.
```python
from pathlib import Path
from fastfold import Client
client = Client()
job = client.jobs.create_from_yaml(
Path("fastfold/examples/fold/boltz2_affinity_input.yaml").read_text(),
model_name="boltz-2",
name="yaml-demo",
)
print(job.id)
```
## Generic workflows
```python
from fastfold import Client
client = Client()
workflow = client.workflows.create(
"calvados_openmm_v1",
{
"name": "openmm_manual_example",
"preset": "single_af_go",
"files": {
"pdb": {
"libraryItemId": "11111111-1111-1111-1111-111111111111",
"fileName": "protein.pdb",
},
"pae": {
"libraryItemId": "22222222-2222-2222-2222-222222222222",
"fileName": "pae.json",
},
},
},
name="OpenMM Manual Example",
)
print(workflow.workflow_id)
print(client.workflows.status(workflow.workflow_id).status)
```
## Use-case helpers
```python
from fastfold import Client
client = Client()
openmm_workflow = client.openmm.submit_from_fold_job(
"00000000-0000-0000-0000-000000000000",
simulation_name="openmm_linked_demo",
)
openmmdl_workflow = client.openmmdl.submit_from_local_files(
topology_path="./protein.pdb",
ligand_paths=["./ligand.sdf"],
simulation_name="openmmdl_demo",
)
boltzgen_draft = client.boltzgen.create_draft(name="boltzgen_demo")
evolla_workflow = client.evolla.submit_from_fold_job(
"00000000-0000-0000-0000-000000000000",
"What is the function of this protein?",
source_user_id="00000000-0000-0000-0000-000000000001",
)
evolla_upload = client.evolla.submit_from_local_file("./structure.cif", "Describe the active site.")
print(
openmm_workflow.workflow_id,
openmmdl_workflow.workflow_id,
boltzgen_draft.workflow_id,
evolla_workflow.workflow_id,
evolla_upload.workflow_id,
)
```
## CLI parity
The CLI now mirrors the same resource model:
```bash
fastfold-cli fold --sequence "LLGDFFRKSKEKIGKEFKRIVQRIKDFLRNLVPRTES" --model boltz-2
fastfold-cli jobs create --payload-file fastfold/examples/fold/job_payload.json
fastfold-cli jobs from-yaml --file fastfold/examples/fold/boltz2_affinity_input.yaml --model boltz-2
fastfold-cli workflows create --payload-file fastfold/examples/openmm/from_manual_files.json
fastfold-cli workflows openmm from-manual-files --pdb ./protein.pdb --pae ./pae.json
fastfold-cli workflows openmmdl from-local-files --topology ./protein.pdb --ligand ./ligand.sdf
fastfold-cli workflows evolla from-fold-job --question "What is the function of this protein?"
fastfold-cli workflows evolla from-file ./protein.cif --question "What is the function of this protein?"
fastfold-cli workflows boltzgen create-draft --name demo
fastfold-cli reports slack --markdown-file fastfold/examples/reports/sample_report.md
```
## Polling, timeouts, and scripts
In scripts and notebooks, prefer waiting for completion to simplify control flow:
```python
results = client.jobs.wait_for_completion(
myJob.id,
poll_interval=5.0, # seconds between polls
timeout=900.0, # seconds until giving up
)
```
If you want to implement your own polling loop, you can treat job status as the source of truth and branch your logic accordingly (see the status list in the Examples page).
## Visibility (public vs private)
```python
client.jobs.set_public(myJob.id, True) # make job publicly accessible
```
## What’s next
* Reference examples by use case (fold, OpenMM, OpenMMDL, Evolla, BoltzGen, reports): [/sdk](/sdk)
# Quick Start
Use this page to get to a first successful run quickly, then move into the deeper product-specific docs.
## Agent CLI
Use Agent CLI when you want Fastfold to interpret prompts, choose tools, and execute multi-step workflows from one terminal session.
### Fast path (install -> setup -> first run)
```bash
uv tool install "fastfold-agent-cli[all]" --python 3.10
fastfold setup
fastfold "Fold this sequence with boltz-2 and show binding pockets: MALWMRLLPLL..."
```
### Everyday quick commands
```bash
fastfold # interactive mode
fastfold doctor # health checks
fastfold --continue # resume last session
```
### Agent CLI references
* Overview and install: [/agents/cli](/agents/cli)
* Setup and local models (Ollama/OpenAI-compatible): [/agents/cli/setup](/agents/cli/setup)
* Quick usage and prompt examples: [/agents/cli/usage](/agents/cli/usage)
* Interactive slash commands: [/agents/cli/interactive-commands](/agents/cli/interactive-commands)
* Skills commands: [/agents/cli/skills](/agents/cli/skills)
* Data/report commands: [/agents/cli/data-reports](/agents/cli/data-reports)
* Troubleshooting: [/agents/cli/troubleshooting](/agents/cli/troubleshooting)
If you want lower-level control for scripts, notebooks, or CI, continue with the SDK path below.
## Python SDK and CLI
If you prefer scriptable control and reproducible pipelines, use the SDK and SDK CLI path.
### Create an API key
Store the key in `FASTFOLD_API_KEY` so both the SDK and CLI pick it up automatically.
macOS / Linux
Windows
```bash
export FASTFOLD_API_KEY="sk-...your-api-key"
```
```bash
setx FASTFOLD_API_KEY "sk-...your-api-key"
```
### Install the package
Requires **Python 3.8+**.
```bash
pip install fastfold-ai
```
### Run a fold in Python
```python
from fastfold import Client
client = Client()
job = client.fold.create(
sequence="LLGDFFRKSKEKIGKEFKRIVQRIKDFLRNLVPRTES",
model="boltz-2",
is_public=True,
)
results = client.jobs.wait_for_completion(job.id, poll_interval=5.0, timeout=900.0)
print("Status:", results.job.status)
print("CIF URL:", results.cif_url())
print("Mean PLDDT:", results.metrics().mean_PLDDT)
print("Viewer:", results.get_viewer_link())
```
### Run a fold from the SDK CLI
```bash
fastfold-cli fold --sequence "LLGDFFRKSKEKIGKEFKRIVQRIKDFLRNLVPRTES" --model boltz-2
```
On success, the SDK CLI prints the created job ID to stdout.
### Move to file-backed and workflow-driven runs
Submit a full job payload file:
```bash
fastfold-cli jobs create --payload-file fastfold/examples/fold/job_payload.json
```
Submit Boltz-style YAML directly:
```bash
fastfold-cli jobs from-yaml --file fastfold/examples/fold/boltz2_affinity_input.yaml --model boltz-2
```
Start an OpenMM workflow from local structure files:
```bash
fastfold-cli workflows openmm from-manual-files --pdb ./protein.pdb --pae ./pae.json --simulation-name AF-P00698 --sim-length-ns 10 --box-length 50
```
Start an OpenMMDL workflow from local topology and ligand files:
```bash
fastfold-cli workflows openmmdl from-local-files --topology ./KEAP1kd.pdb --ligand ./IQK.sdf --simulation-name "KEAP1 + IQK" --input-json fastfold/examples/openmmdl/workflow_input.json
```
Use [/sdk](/sdk) for the full recipe set, including OpenMM, OpenMMDL, BoltzGen, generic workflows, webhooks, and report sharing.
## PyMOL Agent
If your workflow is structure-first, continue with PyMOL Agent for in-app visualization and chat-driven operations.
There are **two install paths**—pick the one that matches how you run PyMOL.
### Open Source install
Use this when you do not already have PyMOL, or you want the Fastfold-managed open source stack (conda + installer script).
```bash
curl -LsSf https://fastfold.ai/pymol-agent/install.sh | sh
```
If PyMOL is already in your environment and you only need the agent:
```bash
curl -LsSf https://fastfold.ai/pymol-agent/install.sh | sh -s -- --agent-only
```
### Commercial PyMOL install
If you use **commercial PyMOL** and prefer **Plugin Manager** installs, use the plugin zip from GitHub Releases instead of the curl installer:
```text
https://github.com/fastfold-ai/fastfold-pymol-agent/releases/latest/download/fastfold-pymol-agent-plugin.zip
```
Install via **Plugin > Plugin Manager > Install New Plugin**, then run `fastfold deps install` from the PyMOL command line once. Full steps: [PyMOL Agent](/agents/pymol).
### Docs and repo
* Guide: [PyMOL Agent](/agents/pymol) (open source vs commercial, first run, troubleshooting)
* Repository: [fastfold-ai/fastfold-pymol-agent](https://github.com/fastfold-ai/fastfold-pymol-agent)
## Next steps
Now that you have a quick path running, use these references to go deeper by integration type.
* **SDK install**: [/sdk/install](/sdk/install)
* **SDK overview and recipes**: [/sdk](/sdk)
* **SDK CLI recipes**: [/sdk/cli](/sdk/cli)
* **Agents overview**: [/agents](/agents)
* **Agent CLI**: [/agents/cli](/agents/cli)
* **PyMOL Agent**: [/agents/pymol](/agents/pymol)
* **API Reference**: [/api](/api)
* **Available models**: [cloud.fastfold.ai/models](https://cloud.fastfold.ai/models)
# Troubleshooting
## Authentication errors
* **401 / Unauthorized**: your API key is missing, invalid, or not being picked up.
* Make sure `FASTFOLD_API_KEY` is set in your shell/session.
* If you're running in a notebook, restart the kernel after setting env vars.
* Try passing the key explicitly to confirm it works:
```python
from fastfold import Client
client = Client(api_key="sk-...your-api-key")
```
## 429 / quota exceeded
All API requests are subject to quota limits. Check the [Usage dashboard](https://cloud.fastfold.ai/usage).
## Timeouts while waiting for completion
If your script hits the timeout, increase it and/or reduce polling load:
```python
results = client.jobs.wait_for_completion(
myJob.id,
poll_interval=10.0,
timeout=3600.0,
)
```
## Job status is FAILED or STOPPED
* **FAILED**: the job encountered an error (invalid input, model constraints, or server error).
* **STOPPED**: the job was stopped before completion.
Recommended pattern in pipelines:
```python
results = client.jobs.wait_for_completion(myJob.id, poll_interval=5.0, timeout=900.0)
if results.job.status != "COMPLETED":
raise RuntimeError(f"Job did not complete: status={results.job.status} job_id={myJob.id}")
```
## Artifact URLs are missing
Artifacts can differ between:
* **Complex jobs**: shared artifacts are available at the top level (e.g. `results.cif_url()`).
* **Non-complex jobs**: artifacts are per-sequence; use indexing (e.g. `results[0].cif_url()`).
See: [/sdk](/sdk)
# Overview
Fastfold agent integrations let you access folding, workflows, and related research operations through conversational or agent-driven interfaces instead of calling the SDK or raw API directly. Use them when you want an agent to interpret requests, coordinate multi-step tasks, and surface Fastfold capabilities inside the tools you already use.
This section covers the main ways to work with Fastfold through agents:
* [Agent CLI](/agents/cli) for terminal-first natural-language research workflows
* [Skills](/agents/skills) for reusable Fastfold capabilities inside supported coding agents
* [PyMOL Agent](/agents/pymol) for chat-driven structure workflows inside PyMOL
## How to choose
* Use [Agent CLI](/agents/cli) when you want one agent to interpret a request, choose tools, and execute a multi-step workflow from the terminal.
* Use [Skills](/agents/skills) when you already work in an agent environment such as Cursor, Claude Code, or Codex and want Fastfold operations exposed there as packaged capabilities.
* Use [PyMOL Agent](/agents/pymol) when structure inspection and visualization inside PyMOL are part of the workflow.
## What each path is best at
### Agent CLI
Best for:
* interactive research sessions in the terminal
* autonomous multi-step analysis
* background task workflows for long-running fold or workflow jobs
* report export and Slack sharing from the same session
### Skills
Best for:
* adding Fastfold workflows to external agent tools or the Fastfold Agent CLI
* standardized create -> wait -> results patterns
* reusable agent automation for folding, MD, BoltzGen, and report sharing
* teams that want the same Fastfold operations available across multiple agent environments
The Agent CLI includes native skill management (`fastfold skills ...`, `/skills-find`, `/skills-add`) plus two bundled helpers (`find-skills`, `skill-creator`). Domain skills install from the [Fastfold catalog](https://github.com/fastfold-ai/skills).
### PyMOL Agent
Best for:
* combining agent guidance with in-app structure visualization
* loading fold or workflow outputs directly into PyMOL
* structure-focused workflows that benefit from interactive inspection
## Relationship to SDK and API
Agents complement the direct integration paths:
* use [/sdk](/sdk) when you want explicit Python or SDK CLI control
* use [/api](/api) when you want raw HTTP integration
* use the agent paths in this section when you want higher-level orchestration or a conversational workflow
## What's next
* New to Fastfold? Follow [/quick-start](/quick-start) to create an API key and run a first fold or workflow, then pick an agent path above.
* Installing the **Agent CLI**: prerequisites, `uv tool install`, Docker, auth, and commands → [/agents/cli](/agents/cli).
* Adding **Skills** to Cursor, Claude Code, or Codex (install, env vars, prompts) → [/agents/skills](/agents/skills).
* **PyMOL Agent** open-source vs commercial install, first run, and troubleshooting → [/agents/pymol](/agents/pymol).
* Prefer Python or HTTP? Use the [SDK](/sdk) or [API reference](/api); agents sit on top of the same jobs and workflows.
# PyMOL Agent
PyMOL Agent is a plugin workflow that combines Fastfold skills with natural-language structure editing.
You can run fold or MD workflows, load generated artifacts into PyMOL, and iterate on visualization in one place.
* **GitHub:** [fastfold-ai/fastfold-pymol-agent](https://github.com/fastfold-ai/fastfold-pymol-agent)
* **Hosted installer:** [https://fastfold.ai/pymol-agent/install.sh](https://fastfold.ai/pymol-agent/install.sh)
***
## Open Source Install
Use this path when you do not already have PyMOL installed, or when you want the standalone Fastfold-managed open source setup.
```bash
curl -LsSf https://fastfold.ai/pymol-agent/install.sh | sh
```
If you already have the target environment and only want the agent:
```bash
curl -LsSf https://fastfold.ai/pymol-agent/install.sh | sh -s -- --agent-only
```
To override the conda environment name:
```bash
curl -LsSf https://fastfold.ai/pymol-agent/install.sh | sh -s -- --env-name myenv
```
Then launch PyMOL from that environment:
```bash
conda activate myenv
pymol
```
## Commercial PyMOL Install
If you use commercial PyMOL and prefer Plugin Manager installs, install the plugin zip from GitHub Releases.
Latest release asset:
```text
https://github.com/fastfold-ai/fastfold-pymol-agent/releases/latest/download/fastfold-pymol-agent-plugin.zip
```
In PyMOL:
1. Open **Plugin > Plugin Manager > Install New Plugin**.
2. Choose **Install from PyMOLWiki or any URL**.
3. Paste the plugin zip URL above and fetch it.
4. Open the plugin from the Plugins menu.
5. Install Python dependencies once from the PyMOL command line:
```text
fastfold deps install
```
You can also download that zip locally and install it through **Install from local file**.
***
## First Run In PyMOL
After PyMOL opens, run:
```text
fastfold doctor
fastfold setup anthropic
fastfold setup fastfold
fastfold ui
```
Get keys:
* Fastfold API keys: [https://cloud.fastfold.ai/api-keys](https://cloud.fastfold.ai/api-keys)
* Anthropic dashboard: [https://platform.claude.com/dashboard](https://platform.claude.com/dashboard)
The setup flow stores your Anthropic key for the agent backend and your Fastfold API key for running Fastfold skills and workflows from PyMOL.
***
## Example Workflow
```text
Use esm1b in Fastfold to run a fold job for my sequence, wait for completion,
load the resulting structure in PyMOL, then show cartoon and color by secondary structure.
```
Use the chat UI for fold jobs, MD workflows, artifact loading, and iterative structure edits without leaving PyMOL.
You can track submitted jobs in your account dashboard: [https://cloud.fastfold.ai/jobs](https://cloud.fastfold.ai/jobs).
***
## Next steps
* Terminal-based research workflows: [Agent CLI](/agents/cli)
* Scripted automation and API usage: [SDK Install](/sdk/install)
* Skill-based agent integrations: [Skills](/agents/skills)
# Skills
Fastfold skills are packaged instructions and scripts that help AI agents run common workflows end-to-end.
Built on the open [Agent Skills](https://www.skills.sh/) ecosystem from Vercel, they work across many agent tools, including the **Fastfold Agent CLI**, Claude Code, Cursor, Codex, GitHub Copilot, Gemini, and others. See [skills.sh](https://www.skills.sh/) for the current list of supported agents.
Skill directories and `name:` frontmatter use **snake\_case** (for example `md_openmm_calvados`, `protein_design_boltzgen`). Install with the same name or the `owner/repo@skills/` subpath.
## Install
Skills CLI (any agent)
Fastfold Agent CLI
```bash
npx skills add fastfold-ai/skills # all skills
npx skills add fastfold-ai/skills --skill fold # one skill
```
```bash
fastfold skills add fastfold-ai/skills # all skills
fastfold skills add fastfold-ai/skills@skills/fold # one skill
fastfold skills find [query] # browse the live catalog
fastfold skills list # installed + bundled skills
fastfold skills info fold # show details
fastfold skills upgrade # sync catalog + update installed
fastfold skills remove fold # remove one skill
fastfold skills delete --all # remove ALL user-installed skills (asks to confirm)
```
In interactive Agent CLI sessions, use `/skills`, `/skills-find`, `/skills-add`, `/skills-upgrade`, and `/skills-remove`. The agent can also discover and install skills when you enable `fastfold config set skills.allow_agent_install true`.
`fastfold setup` includes a skills step: it live-fetches the Fastfold catalog (all skills preselected), suggests community collections, and accepts custom sources. Non-interactive: `fastfold setup --skills "fastfold-ai/skills@skills/fold,..."` or `--skip-skills`.
Repository: [github.com/fastfold-ai/skills](https://github.com/fastfold-ai/skills)\
Listing: [skills.sh/fastfold-ai/skills](https://skills.sh/fastfold-ai/skills)\
Agent CLI skill management: [Agent CLI guide](/agents/cli#skills)
### Install method and location (Agent CLI)
* When **Node/`npx`** is available, installs prefer `npx skills add` into a Fastfold-owned dir (`~/.fastfold-cli/.claude/skills`).
* Otherwise a native **`git clone`** installs into `~/.fastfold-cli/skills`.
* Both locations are discovered automatically from any working directory.
### Versioning and updates (Agent CLI)
The Fastfold catalog is published with GitHub Releases (one semver tag per catalog version), and the CLI surfaces that release as a version.
* `fastfold skills list` (and `/skills`) show **Author**, **Updated**, and **Version**. The version is the catalog's latest release tag (for example `v1.0.0`) and the author is the source repo org (for example `fastfold-ai`). Sources without a release — npx-installed or bundled helper skills — show `Version not available`.
* Run `fastfold skills upgrade` (or `/skills-upgrade`) to sync the catalog and update installed skills to the latest release.
* On launch the CLI shows a non-blocking notice when a newer catalog release is available (`Skills update available: v1.0.0 -> v1.1.0 Run /skills-upgrade`). The check reads a local cache and refreshes in the background, so it never slows startup.
### Community skill collections
Install whole collections from other providers:
```bash
fastfold skills add K-Dense-AI/scientific-agent-skills # K-Dense-AI
fastfold skills add anthropics/life-sciences # Anthropic
fastfold skills add google-deepmind/science-skills # DeepMind
```
The catalog grows over time — run `fastfold skills find` (or `/skills-find`) to see what is available now.
## Bundled vs installable (Agent CLI)
Only two helper skills ship bundled with the Agent CLI:
| Skill | Purpose |
| --------------- | ------------------------------------------------------------------------------------------------ |
| `find-skills` | Discover skills from the Fastfold catalog and the open skills.sh ecosystem |
| `skill-creator` | Scaffold, validate, and package new skills (`python scripts/.py` from the skill directory) |
Domain skills (`boltz`, `fold`, `md_openmm_calvados`, `md_openmmdl`, `protein_design_boltzgen`, `slack_report`, and future catalog additions) are **installable, not bundled**. Install them from the [Fastfold catalog](https://github.com/fastfold-ai/skills) before use.
### Running skill scripts
Skill scripts are portable and self-contained. From a skill's directory:
```bash
python scripts/.py
```
In the Agent CLI, the installed-skills section of the system prompt shows each skill's absolute directory and rewrites script paths so the agent can invoke them correctly.
## Available skills (Fastfold catalog)
| Skill | Primary use |
| ------------------------- | --------------------------------------------------------------------------------------------- |
| `boltz` | Direct Boltz API workflows (SAB, protein/small-molecule design/screen, ADME, status/recovery) |
| `fold` | Fastfold Jobs API folding pipelines (create -> wait -> results) |
| `protein_design_boltzgen` | BoltzGen protein design workflow orchestration and result ranking |
| `md_openmm_calvados` | CALVADOS + OpenMM MD workflows from fold or manual inputs |
| `md_openmmdl` | OpenMMDL protein-ligand MD workflows and analysis outputs |
| `slack_report` | Share report markdown to Slack and save a library copy |
### `boltz`
Direct Boltz API automation that drives the official `boltz-api` CLI for structure-and-binding, protein/small-molecule design and screen, ADME, and status/recovery.
Use it when you need:
* direct `boltz-api` execution instead of Fastfold Jobs/Workflows wrappers
* an estimate -> confirm -> submit -> wait/download flow (it always estimates and waits for your approval before any billable run)
* durable artifacts and API-based recovery: locally it writes into the agent output dir (`${OUTPUT_DIR:-./outputs}/boltz`); in a hosted sandbox it downloads to `/tmp` and persists to the S3-backed `/workspace` with `scripts/persist.sh`
Requires `BOLTZ_API_KEY` (see [API key setup](#api-key-setup)).
Install:
```bash
fastfold skills add fastfold-ai/skills@skills/boltz
```
References:
* Skill: [skills/boltz/SKILL.md](https://github.com/fastfold-ai/skills/blob/main/skills/boltz/SKILL.md)
* Persistence helper: [skills/boltz/scripts/persist.sh](https://github.com/fastfold-ai/skills/blob/main/skills/boltz/scripts/persist.sh)
* API mapping: [skills/boltz/references/api.md](https://github.com/fastfold-ai/skills/blob/main/skills/boltz/references/api.md)
* Results/runtime behavior: [skills/boltz/references/results.md](https://github.com/fastfold-ai/skills/blob/main/skills/boltz/references/results.md)
* Quick examples: [skills/boltz/references/examples.md](https://github.com/fastfold-ai/skills/blob/main/skills/boltz/references/examples.md)
Example prompts:
```text
Run a simple ROR1-style Boltz-2 structure-and-binding smoke test with aspirin; estimate first, then execute.
```
```text
Run a minimal AMBP-style protein design job with 10 proteins and return top metrics and artifact paths.
```
```text
Screen aspirin, ibuprofen, and caffeine against a PknB-style target with small-molecule library screen and summarize top hits.
```
```text
Run ADME quick triage for aspirin, ibuprofen, phenol, and caffeine and report lipophilicity/permeability/solubility.
```
```text
Recover this Boltz job by ID (retrieve) and resume local artifacts with run name sms-pknb-demo.
```
### `fold`
Fastfold Jobs API automation for protein folding.
Use it when you need:
* protein sequence folding with Fastfold
* API or script-based job orchestration
* automated create -> wait -> fetch pipelines
Install:
```bash
fastfold skills add fastfold-ai/skills@skills/fold
```
References:
* Skill: [skills/fold/SKILL.md](https://github.com/fastfold-ai/skills/blob/main/skills/fold/SKILL.md)
* Auth/API: [skills/fold/references/auth\_and\_api.md](https://github.com/fastfold-ai/skills/blob/main/skills/fold/references/auth_and_api.md)
* Schema summary: [skills/fold/references/schema\_summary.md](https://github.com/fastfold-ai/skills/blob/main/skills/fold/references/schema_summary.md)
* OpenAPI reference: [skills/fold/references/jobs.yaml](https://github.com/fastfold-ai/skills/blob/main/skills/fold/references/jobs.yaml)
### `md_openmm_calvados`
CALVADOS + OpenMM workflow automation via Workflows API (`calvados_openmm_v1`).
Use it when you need:
* fold -> OpenMM linked simulation flows
* manual PDB + PAE submission for MD simulation
* MD metrics, artifacts, and result polling
Install:
```bash
fastfold skills add fastfold-ai/skills@skills/md_openmm_calvados
```
References:
* Skill: [skills/md\_openmm\_calvados/SKILL.md](https://github.com/fastfold-ai/skills/blob/main/skills/md_openmm_calvados/SKILL.md)
* Auth/API: [skills/md\_openmm\_calvados/references/auth\_and\_api.md](https://github.com/fastfold-ai/skills/blob/main/skills/md_openmm_calvados/references/auth_and_api.md)
* Schema summary: [skills/md\_openmm\_calvados/references/schema\_summary.md](https://github.com/fastfold-ai/skills/blob/main/skills/md_openmm_calvados/references/schema_summary.md)
* Method details: [skills/md\_openmm\_calvados/references/calvados\_method.md](https://github.com/fastfold-ai/skills/blob/main/skills/md_openmm_calvados/references/calvados_method.md)
### `md_openmmdl`
OpenMMDL protein-ligand molecular dynamics workflow automation via Workflows API (`openmmdl_v1`).
Use it when you need:
* topology + ligand-driven MD workflow submission
* draft script preparation + execution for OpenMMDL
* analysis outputs, trajectory artifacts, and frame extraction
Install:
```bash
fastfold skills add fastfold-ai/skills@skills/md_openmmdl
```
References:
* Skill: [skills/md\_openmmdl/SKILL.md](https://github.com/fastfold-ai/skills/blob/main/skills/md_openmmdl/SKILL.md)
* Auth/API: [skills/md\_openmmdl/references/auth\_and\_api.md](https://github.com/fastfold-ai/skills/blob/main/skills/md_openmmdl/references/auth_and_api.md)
* Schema summary: [skills/md\_openmmdl/references/schema\_summary.md](https://github.com/fastfold-ai/skills/blob/main/skills/md_openmmdl/references/schema_summary.md)
### `protein_design_boltzgen`
BoltzGen protein design workflow automation (draft -> graph upsert -> review -> execute -> ranked results).
Use it when you need:
* single-spec or multi-spec BoltzGen design flows
* example-first workflow setup from bundled local preset files
* candidate metrics interpretation and per-candidate Mol\* result links
* API-only workflow orchestration that mirrors Composer behavior
Install:
```bash
fastfold skills add fastfold-ai/skills@skills/protein_design_boltzgen
```
References:
* Skill: [skills/protein\_design\_boltzgen/SKILL.md](https://github.com/fastfold-ai/skills/blob/main/skills/protein_design_boltzgen/SKILL.md)
* Workflow helper script: [skills/protein\_design\_boltzgen/scripts/workflow\_api.py](https://github.com/fastfold-ai/skills/blob/main/skills/protein_design_boltzgen/scripts/workflow_api.py)
* YAML keys: [skills/protein\_design\_boltzgen/references/yaml\_keys.md](https://github.com/fastfold-ai/skills/blob/main/skills/protein_design_boltzgen/references/yaml_keys.md)
* Preset examples: [skills/protein\_design\_boltzgen/references/examples/README.md](https://github.com/fastfold-ai/skills/blob/main/skills/protein_design_boltzgen/references/examples/README.md)
* Metrics guide: [skills/protein\_design\_boltzgen/references/metrics\_guide.md](https://github.com/fastfold-ai/skills/blob/main/skills/protein_design_boltzgen/references/metrics_guide.md)
### `slack_report`
Share CLI markdown reports to Slack and save a library copy in Fastfold Cloud.
Use it when you need:
* share a markdown report to Slack
* keep a saved copy in Fastfold library
* give teammates a quick link to open the saved report
Install:
```bash
fastfold skills add fastfold-ai/skills@skills/slack_report
```
References:
* Skill: [skills/slack\_report/SKILL.md](https://github.com/fastfold-ai/skills/blob/main/skills/slack_report/SKILL.md)
* API reference: [skills/slack\_report/references/api.md](https://github.com/fastfold-ai/skills/blob/main/skills/slack_report/references/api.md)
## Example prompts
After installing, ask your agent directly:
```text
Use Boltz-2 in Fastfold with affinity property to the ligand. Fold this protein: PQITLWQRPLVTIKIGGQLKEALLDTGADDTVLEEMSLPGRWKPKMIGGIGGFIKVRQYDQILIEICGHKAIGTVLVGPTPVNIIGRNLLTQIGCTLNF and this ligand: CC1CN(CC(C1)NC(=O)C2=CC=CC=C2N)C(=O)NC(C)(C)C
```
```text
Use Boltz API directly to run structure-and-binding for this target+ligand payload, estimate cost first, then execute and return persistent artifact paths.
```
```text
Run an OpenMM simulation from my completed fold job and return metrics, plots, and the dashboard link.
```
```text
Run an OpenMMDL simulation with topology + ligand inputs and return analysis outputs with links.
```
```text
Help me run a quick BoltzGen smoke test for a simple peptide binder against 5CQG, and show me the draft before running.
```
```text
Show me BoltzGen protein design examples and run vanilla_target_binding_site with one target and one budget in the background. Keep the workflow_id for follow-up results.
```
```text
Share the current report to Slack and save a copy in my Fastfold library.
```
## API key setup
These skills run against two compute providers. Set the key for whichever skills you use.
| Provider | API key | Used by | Get a key |
| ------------------------------------- | ------------------ | -------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Fastfold Cloud (Jobs & Workflows API) | `FASTFOLD_API_KEY` | `fold`, `protein_design_boltzgen`, `md_openmm_calvados`, `md_openmmdl`, `slack_report` | [cloud.fastfold.ai/api-keys](https://cloud.fastfold.ai/api-keys) |
| Boltz API | `BOLTZ_API_KEY` | `boltz` | [Boltz Console](https://api.boltz.bio/console), or enable the [Fastfold Boltz provider](https://cloud.fastfold.ai/integrations/providers?provider=boltz) |
### Option A: `.env` (recommended)
Your agent can help you create these files and follow the setup.
```bash
cp skills/fold/references/.env.example .env
```
Then edit `.env`, setting only the key(s) for the providers you use:
```dotenv
FASTFOLD_API_KEY=sk-your-actual-key-here
BOLTZ_API_KEY=sk-your-boltz-key-here
```
### Option B: shell environment
```bash
export FASTFOLD_API_KEY="sk-..."
export BOLTZ_API_KEY="sk-..."
```
Environment variables take precedence over `.env`. In a hosted sandbox, set the variable and restart the session so it becomes visible.
## Slack setup for `slack_report`
Before using `/export-share`, connect Slack and set a channel in Fastfold Cloud:
* [cloud.fastfold.ai/integrations/slack](https://cloud.fastfold.ai/integrations/slack)
Set or confirm the channel for the `agent_cli_report` mode.
## Security note
Keep API keys local and never commit `.env` files.
# Create Job
{/* This file was generated by Fumadocs. Do not edit this file directly. Any changes should be made by running the generation command again. */}
Create a new job to fold protein sequences using AI models. The job will be processed
asynchronously and you can track its status using the returned job ID.
# Get Job Results
{/* This file was generated by Fumadocs. Do not edit this file directly. Any changes should be made by running the generation command again. */}
Fetch job + latest job run + sequences for a job ID.
* If the job is **public** (`isPublic: true`), authentication is **not required**.
* If the job is **not public** (`isPublic: false` or `null`), authentication is required and the caller must own the job.
# Update Job Public Visibility
{/* This file was generated by Fumadocs. Do not edit this file directly. Any changes should be made by running the generation command again. */}
Update a job's `isPublic` flag.
Authentication is required and **only the job owner** can change this field.
# Create Library Item
Create a new library folder or file record.
# Get Library Item
Fetch a single library item by ID. Folder items include nested children.
# List Library
List root-level library items with filtering and cursor pagination.
# Replace Library Item File
Replace a file on an existing library item by filename.
# Search Library
Search library items by name with optional recent-mode behavior.
# Upload Files to Library Item
Upload one or more files to an existing library item folder.
# Custom HTTP Config
Global custom webhook config is user-scoped and managed at:
* `GET /v1/webhooks/custom-http-config`
* `PUT /v1/webhooks/custom-http-config`
* `DELETE /v1/webhooks/custom-http-config`
This page covers the global configuration endpoints. For per-run SDK and CLI usage, see [SDK Webhooks](/sdk/webhooks).
## GET config
```bash
curl -sS -X GET "https://api.fastfold.ai/v1/webhooks/custom-http-config" \
-H "Authorization: Bearer $FASTFOLD_API_KEY"
```
Example response:
```json
{
"user_id": "9a361e2b-0d22-4f08-8f26-c3c7a1266e48",
"is_active": true,
"enabled_by_default": true,
"target_url": "https://example.com/fastfold/hooks",
"token_header": "X-Webhook-Token",
"http_auth_mode": "x_webhook_token",
"has_token": true,
"secret_token_masked": "whk_********************9k2a",
"secret_rotated_at": "2026-04-23T17:31:48.224Z",
"updated_at": "2026-04-23T17:31:48.224Z",
"is_configured": true
}
```
## PUT config
```bash
curl -sS -X PUT "https://api.fastfold.ai/v1/webhooks/custom-http-config" \
-H "Authorization: Bearer $FASTFOLD_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"target_url": "https://example.com/fastfold/hooks",
"token_value": "whk_very_strong_secret",
"enabled_by_default": true
}'
```
Request fields:
* `target_url` (required)
* `token_value` (optional on update, required for first-time usable config)
* `enabled_by_default` (optional bool)
## DELETE config
```bash
curl -sS -X DELETE "https://api.fastfold.ai/v1/webhooks/custom-http-config" \
-H "Authorization: Bearer $FASTFOLD_API_KEY"
```
This deactivates global custom webhook delivery for future runs unless configured again.
# Enable Webhooks
Use this page to enable webhook automation at submit time.
If you want end-to-end SDK or CLI examples for the same payload shapes, see [SDK Webhooks](/sdk/webhooks).
## Fold job payload (`POST /v1/jobs`)
Enable webhooks under `constraints.webhooks`.
### Evolla webhook example
```json
{
"name": "Fold with Evolla webhook",
"sequences": [{ "proteinChain": { "sequence": "MGLSD..." } }],
"params": { "modelName": "boltz-2" },
"constraints": {
"webhooks": {
"evolla": {
"enabled": true,
"initial_question": "What is the function of this protein?"
}
}
}
}
```
### OpenMM webhook example
```json
{
"name": "Fold with OpenMM webhook",
"sequences": [{ "proteinChain": { "sequence": "MGLSD..." } }],
"params": { "modelName": "boltz-2" },
"constraints": {
"webhooks": {
"openmm": {
"enabled": true,
"preset": "single_af_go",
"residue_profile": "calvados3",
"temp": 293.15,
"ionic": 0.15,
"pH": 7.5,
"step_size_ns": 0.01,
"sim_length_ns": 10
}
}
}
}
```
### Custom HTTP webhook (per-run toggle)
```json
{
"constraints": {
"webhooks": {
"custom_http": {
"enabled": true
}
}
}
}
```
When URL/token are not provided in payload, Fastfold resolves them from global custom webhook config when available.
## Workflow payload (`POST /v1/workflows`)
For workflow runs (Evolla/OpenMM), enable custom webhook under `workflow_input.webhooks`.
```json
{
"workflow_name": "calvados_openmm_v1",
"name": "OpenMM with webhook",
"workflow_input": {
"preset": "single_af_go",
"name": "my-openmm-run",
"webhooks": {
"custom_http": {
"enabled": true
}
}
}
}
```
## Default behavior notes
* If global custom webhook is configured with `enabled_by_default: true`, new fold/workflow runs can emit webhook events even when no explicit webhook object is passed.
* If webhook is enabled but not configured (missing URL/token), request validation can fail with a helpful setup error.
# Event Payloads
When `target_kind=custom_http`, Fastfold sends a JSON payload like:
Use [SDK Webhooks](/sdk/webhooks) when you need recipe-style examples for enabling these events from fold or workflow submits.
```json
{
"event": {
"id": "40eac6d4-e841-4d63-a35e-1a85f5cf26d8",
"source_kind": "workflow",
"event_name": "on_complete",
"status": "COMPLETED",
"source_id": "af2473ef-820d-44df-98fe-fa15103157d5",
"occurred_at": "2026-04-23T17:50:10.240Z",
"payload": {}
},
"mapping": {},
"source": {}
}
```
## Top-level fields
* `event`: normalized event envelope
* `mapping`: subscription input mapping (if any)
* `source`: enriched source context
* `source_enrichment_error`: present when enrichment fails but delivery still proceeds
## Fold source enrichment (`source_kind=fold_job`)
For fold events, `source` includes:
* `job`: fold job metadata
* `job_run`: run metadata and selected params
* `input`: run constraints + model parameters used
* `results[]`: per-sequence status, prediction metrics, and signed artifact URLs (`cif_url`, `pdb_url`, `pae_plot_url`, `plddt_plot_url`, `metrics_json_url`, etc.)
Minimal fold example:
```json
{
"source": {
"job": { "id": "job-uuid", "name": "My Fold", "status": "COMPLETED" },
"job_run": { "id": "run-uuid", "model_name": "boltz-2", "weight_set": "Boltz-2" },
"input": {
"constraints": { "webhooks": { "evolla": { "enabled": true } } },
"parameters": { "model_name": "boltz-2", "method": "Boltz-2", "seed": "1" }
},
"results": [
{
"sequence_id": "seq-uuid",
"sequence_type": "protein",
"prediction": { "mean_plddt": 87.1, "ptm_score": 0.71 },
"artifacts": { "cif_url": "https://...", "metrics_json_url": "https://..." }
}
]
}
}
```
## Workflow source enrichment (`source_kind=workflow`)
For workflow events, `source` includes:
* `workflow`: workflow-level status/counts/type
* `input`: workflow input payload
* `tasks[]`: task status/type/result payloads
* `metrics[]`: extracted metrics from task outputs
* `plots[]`: extracted plot-like outputs/artifacts
Minimal workflow example:
```json
{
"source": {
"workflow": {
"id": "workflow-uuid",
"workflow_type": "calvados_openmm_v1",
"status": "COMPLETED",
"tasks_total_count": 1,
"tasks_completed_count": 1
},
"input": {
"input_payload": {
"preset": "single_af_go",
"sim_length_ns": 10,
"webhooks": { "custom_http": { "enabled": true } }
}
},
"tasks": [
{
"task_id": "task-uuid",
"task_type": "inference_calvados_openmm",
"status": "COMPLETED",
"result_raw_json": { "metrics": { "rmsd": {} } }
}
],
"metrics": [{ "task_id": "task-uuid", "metrics": { "rmsd": {} } }],
"plots": [{ "task_id": "task-uuid", "path": "analysis/rmsd.png", "url": "https://..." }]
}
}
```
# Webhook Overview
Fastfold supports webhook-driven automation for both:
* **fold job lifecycle events** (`source_kind: fold_job`)
* **workflow lifecycle events** (`source_kind: workflow`)
Use webhooks when you want downstream actions like:
* auto-create Evolla chat runs after fold completion
* auto-create OpenMM runs after fold completion
* post event payloads to your own HTTPS endpoint
For SDK and CLI recipes that enable these webhook flows in real submit payloads, see [SDK Webhooks](/sdk/webhooks).
## Authentication
All webhook configuration endpoints use normal API auth:
```bash
Authorization: Bearer
```
For custom destination delivery, Fastfold sends your configured token in:
```bash
X-Webhook-Token:
```
## Event model
Webhook events are normalized around:
* `source_kind`: `fold_job` or `workflow`
* `event_name`: `on_complete` or `on_failed`
* `status`: terminal state (`COMPLETED` / `FAILED` etc.)
## Delivery modes
You can use webhook automation in two ways:
1. **Per-run enablement**\
Set webhook fields in job/workflow inputs (for example `constraints.webhooks.*` on fold jobs, or `workflow_input.webhooks.*` on workflows).
2. **Global custom webhook default**\
Configure `/v1/webhooks/custom-http-config` and set `enabled_by_default: true` so new runs inherit custom webhook delivery without explicitly passing webhook fields each time.
## Internal event ingest (for platform operators)
Fastfold internally bridges runtime events to:
* `POST /v1/webhooks/events/ingest`
This endpoint requires:
```bash
X-Webhook-Ingest-Secret:
```
It is not meant for normal external API clients.
# SDK CLI
Use `fastfold-cli` for shell-friendly workflows with IDs by default and JSON output available via `--json`.
Tip: Use `--help` aggressively. The SDK CLI is organized into resource groups, so `fastfold-cli --help`, `fastfold-cli jobs --help`, or `fastfold-cli workflows evolla --help` are the fastest way to discover the exact flags for a task.
## Discover commands
Use these help entry points first:
```bash
fastfold-cli --help
fastfold-cli fold --help
fastfold-cli jobs --help
fastfold-cli library --help
fastfold-cli workflows --help
fastfold-cli workflows openmm --help
fastfold-cli workflows openmmdl --help
fastfold-cli workflows evolla --help
fastfold-cli workflows boltzgen --help
fastfold-cli reports --help
```
Common cross-command flags:
* `--api-key` overrides `FASTFOLD_API_KEY`
* `--base-url` points the CLI at a different Fastfold deployment
* `--timeout` controls HTTP timeout in seconds
* `--json` prints the full API response instead of the default ID or simplified output
Payload and file input patterns used across the CLI:
* `--payload` for inline JSON or YAML objects
* `--payload-file` for JSON or YAML files
* `--file -` or `--payload-file -` to read from stdin
* `--format auto|json|yaml` when you need to force payload parsing
## Command tree
Top-level commands:
```text
fastfold-cli fold
fastfold-cli jobs ...
fastfold-cli library ...
fastfold-cli workflows ...
fastfold-cli reports ...
```
`jobs` subcommands:
```text
fastfold-cli jobs create
fastfold-cli jobs from-yaml
fastfold-cli jobs results
fastfold-cli jobs wait
fastfold-cli jobs set-public
fastfold-cli jobs render-yaml
fastfold-cli jobs render-json
```
`library` subcommands:
```text
fastfold-cli library create
fastfold-cli library get
fastfold-cli library upload
```
`workflows` subcommands:
```text
fastfold-cli workflows create
fastfold-cli workflows get
fastfold-cli workflows status
fastfold-cli workflows task-results
fastfold-cli workflows execute
fastfold-cli workflows set-public
fastfold-cli workflows create-graph
fastfold-cli workflows get-yml
fastfold-cli workflows set-yml
fastfold-cli workflows create-from-yml
fastfold-cli workflows openmm ...
fastfold-cli workflows openmmdl ...
fastfold-cli workflows evolla ...
fastfold-cli workflows boltzgen ...
```
`workflows evolla` subcommands:
```text
fastfold-cli workflows evolla from-fold-job
fastfold-cli workflows evolla from-file
fastfold-cli workflows evolla from-input
```
`workflows openmm` subcommands:
```text
fastfold-cli workflows openmm from-fold-job
fastfold-cli workflows openmm from-manual-files
fastfold-cli workflows openmm from-workflow
fastfold-cli workflows openmm extract-frame
```
`workflows openmmdl` subcommands:
```text
fastfold-cli workflows openmmdl prepare-script
fastfold-cli workflows openmmdl from-local-files
fastfold-cli workflows openmmdl from-workflow
fastfold-cli workflows openmmdl execute-draft
fastfold-cli workflows openmmdl extract-frame
```
`workflows boltzgen` subcommands:
```text
fastfold-cli workflows boltzgen create-draft
fastfold-cli workflows boltzgen create-from-yml
fastfold-cli workflows boltzgen get-yml
fastfold-cli workflows boltzgen set-yml
fastfold-cli workflows boltzgen execute
fastfold-cli workflows boltzgen logs
fastfold-cli workflows boltzgen example-files
fastfold-cli workflows boltzgen build-spec
```
`reports` subcommands:
```text
fastfold-cli reports slack
```
## Fold jobs
```bash
fastfold-cli fold --sequence "LLGDFFRKSKEKIGKEFKRIVQRIKDFLRNLVPRTES" --model boltz-2
fastfold-cli jobs create --payload-file fastfold/examples/fold/job_payload.json
fastfold-cli jobs from-yaml --file fastfold/examples/fold/boltz2_affinity_input.yaml --model boltz-2
fastfold-cli jobs results --json
fastfold-cli jobs wait --json
fastfold-cli jobs set-public --public
fastfold-cli jobs render-yaml --payload-file fastfold/examples/fold/job_payload.json
fastfold-cli jobs render-json --payload-file fastfold/examples/fold/boltz2_affinity_input.yaml --format yaml --json
```
Common fold and job flags:
* `fold --params` accepts inline JSON or YAML for advanced model parameters
* `fold --constraints` accepts inline JSON or YAML for constraints
* `jobs create --from-id` and `jobs from-yaml --from-id` associate the job with a library item
* `jobs from-yaml --draft` creates without dispatching immediately
* `jobs from-yaml --public` sets public visibility at creation time
* `jobs wait --poll-interval`, `--wait-timeout`, and `--no-log` control wait behavior
## Workflows
```bash
fastfold-cli workflows create --payload-file fastfold/examples/openmm/from_manual_files.json
fastfold-cli workflows get --json
fastfold-cli workflows status
fastfold-cli workflows task-results --json
fastfold-cli workflows execute
fastfold-cli workflows set-public --public
fastfold-cli workflows create-graph --workflow-name boltzgen_v1 --name demo
fastfold-cli workflows get-yml
fastfold-cli workflows set-yml --file ./workflow.yml --json
fastfold-cli workflows create-from-yml --workflow-name boltzgen_v1 --file ./workflow.yml --execute --json
```
Use the generic `workflows` commands when you already have a complete request body or when you need direct `workflow.yml` control.
## OpenMM and OpenMMDL helpers
```bash
fastfold-cli workflows openmm from-fold-job --sim-length-ns 0.2
fastfold-cli workflows openmm from-manual-files --pdb ./protein.pdb --pae ./pae.json --simulation-name AF-P00698 --sim-length-ns 10 --box-length 50
fastfold-cli workflows openmm from-workflow --input-json '{"sim_length_ns": 5}'
fastfold-cli workflows openmm extract-frame --time-ns 10 --json
fastfold-cli workflows openmmdl prepare-script --input-json fastfold/examples/openmmdl/from_local_files.json
fastfold-cli workflows openmmdl from-local-files --topology ./KEAP1kd.pdb --ligand ./IQK.sdf --simulation-name "KEAP1 + IQK" --input-json fastfold/examples/openmmdl/workflow_input.json
fastfold-cli workflows openmmdl from-local-files --topology ./KEAP1kd.pdb --ligand ./IQK.sdf --simulation-name "KEAP1 + IQK (Quick Water Box)" --input-json fastfold/examples/openmmdl/quick_water_box.workflow_input.json
fastfold-cli workflows openmmdl from-workflow --prepare --json
fastfold-cli workflows openmmdl execute-draft --json
fastfold-cli workflows openmmdl extract-frame --time-ns 10 --json
```
Important helper flags:
* `workflows openmm from-workflow --input-json` merges JSON or YAML into `workflow_input`
* `workflows openmmdl from-local-files --ligand` is repeatable
* `workflows openmmdl from-local-files --run-analysis` or `--no-run-analysis` toggles analysis
* `workflows openmmdl from-local-files --skip-prepare` bypasses `/prepare-script`
* `workflows openmmdl from-local-files --draft-script` creates in draft mode
* both `extract-frame` commands accept `--selection`, `--output-filename`, and `--dt-in-ps`
## Evolla helpers
```bash
fastfold-cli workflows evolla from-file ./model.cif --question "What is the function of this protein?" --json
fastfold-cli workflows evolla from-fold-job --question "What is the function of this protein?" --json
fastfold-cli workflows evolla from-input --file fastfold/examples/evolla/from_fold_job.template.json --name "Evolla demo"
```
* `from-file` uploads the structure via the Library API (`file-type` defaults to `protein`) and sets `targetSource: upload`
* `from-fold-job` prefers the CIF URL from job results; if `sourceUserId` cannot be inferred, pass `--source-user-id` or set `FASTFOLD_EVOLLA_SOURCE_USER_ID`
* `from-input` posts a `workflow_input` object as for [Create Workflow Run](/workflows/createWorkflowRun) with `workflow_name: evolla_v1`
## BoltzGen helpers
```bash
fastfold-cli workflows boltzgen create-draft --name demo
fastfold-cli workflows boltzgen create-from-yml --file ./workflow.yml --name demo --execute --json
fastfold-cli workflows boltzgen get-yml
fastfold-cli workflows boltzgen set-yml --file ./workflow.yml --json
fastfold-cli workflows boltzgen execute --json
fastfold-cli workflows boltzgen logs --json
fastfold-cli workflows boltzgen example-files --json
fastfold-cli workflows boltzgen build-spec \
--template-file fastfold/examples/boltzgen/minimal.workflow.yml \
--replacements-file fastfold/examples/boltzgen/replacements.example.json \
--output ./workflow.yml
```
Reminder: `build-spec` only generates the local `workflow.yml`. You still need to upload referenced inputs to the library and then submit or attach the resulting workflow YAML to a draft workflow.
## Library and reports
```bash
fastfold-cli library create --name input-folder --type folder --json
fastfold-cli library get --json
fastfold-cli library upload ./protein.pdb ./ligand.sdf --json
fastfold-cli reports slack --markdown "## Demo Report"
fastfold-cli reports slack --markdown-file fastfold/examples/reports/sample_report.md
```
For `library create`, the main fields are `--name`, `--type file|folder`, `--parent-id`, `--file-type`, `--origin`, and `--metadata`.
For `reports slack`, pass either `--markdown` or `--markdown-file`. Use `--report-name` to label the saved report, and `--no-save-to-library` when you only want delivery without library persistence.
# Overview
The Fastfold SDK is the official Python client for submitting fold jobs, running workflows, uploading supporting files, and reading results from Fastfold programmatically. Use it in notebooks, scripts, services, and CI when you want a higher-level Python interface over the Fastfold API.
This section also covers the companion CLI, which exposes the same platform capabilities in a shell-friendly form for payload files, automation, and quick inspection from the terminal.
Start with [Install](/sdk/install) for package installation, authentication, and base configuration. Then use the pages in this section by task:
* [Fold](/sdk/fold) for fold jobs, typed sequence payloads, YAML submit, result metrics, and common model patterns
* [CLI](/sdk/cli) for shell-oriented commands and payload-file workflows
* [OpenMM](/sdk/openmm), [OpenMMDL](/sdk/openmmdl), [Evolla](/sdk/evolla), and [BoltzGen](/sdk/boltzgen) for workflow-specific helpers
* [Workflows](/sdk/workflows) for generic workflow endpoints and direct `workflow.yml` control
* [Webhooks](/sdk/webhooks) for webhook-enabled submit payloads
* [Report Sharing](/sdk/reports) for Slack report delivery
The SDK surface is organized around a few main entry points:
* `client.fold` and `client.jobs` for fold submission, raw payloads, YAML submit, status, and results
* `client.workflows` for generic workflow creation, execution, task results, and YAML endpoints
* `client.library` for uploads and file references
* `client.openmm`, `client.openmmdl`, `client.evolla`, and `client.boltzgen` for higher-level workflow helpers
* `client.reports` for markdown report sharing
If you need a field the SDK does not model yet, check the `.raw` payload first before dropping to direct HTTP. For webhook configuration endpoints and outgoing event schema, use the webhook reference pages under [/webhooks/overview](/webhooks/overview).
# Install
Requires **Python 3.8+**.
PyPI
Local (project root)
Development (editable)
```bash
pip install fastfold-ai
```
```bash
pip install .
```
```bash
pip install -e .
```
## Authentication
Set your API key in the environment:
macOS / Linux
Windows
```bash
export FASTFOLD_API_KEY="sk-...your-api-key"
```
```bash
setx FASTFOLD_API_KEY "sk-...your-api-key"
```
Then create the client:
```python
from fastfold import Client
client = Client()
```
You can also pass credentials explicitly:
```python
from fastfold import Client
client = Client(api_key="sk-...your-api-key")
```
## Base URL
By default, the SDK targets the Fastfold API. Override it when using a proxy, self-hosted deployment, or test environment:
```python
from fastfold import Client
client = Client(base_url="https://api.fastfold.ai")
```
## Services
The current SDK exposes:
* `client.fold` for the simplest fold-job flow
* `client.jobs` for raw payload creation, YAML submit, results, polling, visibility, and render helpers
* `client.workflows` for generic workflow creation, status, task results, execution, Evolla linked-history helpers, and workflow YAML endpoints
* `client.library` for item creation and file uploads
* `client.openmm`, `client.openmmdl`, `client.evolla`, and `client.boltzgen` for common multi-step workflow flows
* `client.reports` for Slack markdown reports
The package also installs the `fastfold-cli` entrypoint for shell-based usage:
```bash
fastfold-cli --help
fastfold-cli jobs --help
fastfold-cli workflows --help
```
## Your first fold
```python
from fastfold import Client
client = Client()
job = client.fold.create(
sequence="LLGDFFRKSKEKIGKEFKRIVQRIKDFLRNLVPRTES",
model="boltz-2",
is_public=True,
)
print("Job ID:", job.id)
results = client.jobs.wait_for_completion(job.id, poll_interval=5.0, timeout=900.0)
print("Status:", results.job.status)
print("CIF URL:", results.cif_url())
print("Mean PLDDT:", results.metrics().mean_PLDDT)
print("Viewer:", results.get_viewer_link())
```
## Next steps
* Use [Overview](/sdk) for the SDK surface and recommended reading order
* Use [CLI](/sdk/cli) for shell-oriented commands
* Use [Fold](/sdk/fold), [OpenMM](/sdk/openmm), [OpenMMDL](/sdk/openmmdl), [Evolla](/sdk/evolla), or [BoltzGen](/sdk/boltzgen) for task-specific recipes
# Create Workflow Graph
Create a new workflow graph shell. This endpoint supports creating a boltzgen\_v1 workflow.
# Create Workflow Graph From YAML
Creates a BoltzGen draft workflow, replaces its graph from the provided `workflow_yml`, and optionally queues execution immediately.
## Request body
```json
{
"workflow_name": "boltzgen_v1",
"name": "boltzgen_from_yml",
"create_mode": "api",
"workflow_yml": "version: 1\nname: demo\n...",
"execute": true
}
```
## Notes
* Only `boltzgen_v1` is supported on this endpoint.
* The YAML must define exactly one start node and a single connected graph.
* If `execute` is `true`, the response is the queued workflow run payload.
* `position.x` and `position.y` are optional layout coordinates for the Composer/editor view.
* Design-spec input nodes still require real referenced files, typically a design-spec YAML plus uploaded structure files with valid library item IDs.
## Related operations
* [Create Workflow Graph](/workflows/addWorkflowGraph)
* [Set Workflow YAML](/workflows/setWorkflowYml)
* [Execute Workflow](/workflows/executeWorkflow)
# Create Workflow Run
Create a workflow run. This is the primary endpoint used to start evolla\_v1 and calvados\_openmm\_v1.
# Execute Workflow
Start execution for an existing workflow by ID.
# Get Evolla Linked History
Get linked Evolla history rows for a specific fold job/run/sequence triplet. This is the primary endpoint used by webhook waiters.
# Get Evolla Linked Previews
List latest linked Evolla workflow previews grouped by source sequence for a fold job/run.
# Get Public Workflow Run
Retrieve a publicly shared workflow run without requiring workspace write access.
# Get Workflow Logs
Get workflow logs. Terminal workflows return stored log file text directly.
# Get Workflow Run
Retrieve a workflow run by ID, including task rows and persisted input\_payload.
# Get Workflow Status
Retrieve workflow-level status and task-level states.
# Get Workflow Task Results
Get task outputs and parsed results for a workflow. For BoltzGen metrics, artifacts, and If / Else CEL, see{' '}
BoltzGen SDK. For OpenMM / OpenMMDL outputs and declared metrics, see{' '}
OpenMM and OpenMMDL. For Evolla chat turns stored on tasks, see{' '}
Evolla.
# Get Workflow YAML
Get the current workflow graph serialized as workflow\.yml.
# Workflows Overview
This page gives a single endpoint map for the Workflows API and links to each operation page.
## Authentication
Use your Fastfold API key:
```bash
Authorization: Bearer
```
## Endpoint map
The workflow endpoints documented below are sourced from `openapi/workflows.yaml`.
| Method | Path | Purpose | Docs |
| ------- | --------------------------------------------------- | --------------------------------------------------------------------------------- | ------------------------------------------------------------------------------ |
| `POST` | `/v1/workflows` | Create a workflow run (`evolla_v1`, `calvados_openmm_v1`, `boltzgen_v1`) | [Create Workflow Run](/workflows/createWorkflowRun) |
| `GET` | `/v1/workflows/{workflow_id}` | Fetch workflow run details | [Get Workflow Run](/workflows/getWorkflowRun) |
| `PATCH` | `/v1/workflows/{workflow_id}/public` | Toggle public visibility | [Update Workflow Public](/workflows/updateWorkflowPublic) |
| `GET` | `/v1/workflows/public/{workflow_id}` | Read a public workflow run | [Get Public Workflow Run](/workflows/getPublicWorkflowRun) |
| `POST` | `/v1/workflows/graph/add` | Create graph shell (used by `boltzgen_v1`) | [Create Workflow Graph](/workflows/addWorkflowGraph) |
| `POST` | `/v1/workflows/graph/from-yaml` | Create `boltzgen_v1` graph workflow from `workflow.yml` in one step | [Create Workflow Graph From YAML](/workflows/createWorkflowGraphFromYaml) |
| `GET` | `/v1/workflows/{workflow_id}/workflow.yml` | Get serialized workflow YAML | [Get Workflow YAML](/workflows/getWorkflowYml) |
| `POST` | `/v1/workflows/{workflow_id}/workflow.yml` | Replace graph from workflow YAML | [Set Workflow YAML](/workflows/setWorkflowYml) |
| `POST` | `/v1/workflows/execute` | Execute a workflow by ID | [Execute Workflow](/workflows/executeWorkflow) |
| `GET` | `/v1/workflows/status/{workflow_id}` | Fetch workflow + task statuses | [Get Workflow Status](/workflows/getWorkflowStatus) |
| `GET` | `/v1/workflows/logs/{workflow_id}` | Fetch workflow logs | [Get Workflow Logs](/workflows/getWorkflowLogs) |
| `GET` | `/v1/workflows/task-results/{workflow_id}` | Fetch parsed task outputs and library artifacts | [Get Workflow Task Results](/workflows/getWorkflowTaskResults) |
| `POST` | `/v1/workflows/node/output-schema` | Declared metric keys and artifact names for graph tasks (BoltzGen composer / CEL) | [BoltzGen SDK](/sdk/boltzgen) · [OpenMM](/sdk/openmm) |
| `GET` | `/v1/workflows/evolla/linked-previews` | List linked Evolla previews for a fold source | [Get Evolla Linked Previews](/workflows/getEvollaLinkedPreviews) |
| `GET` | `/v1/workflows/evolla/linked-history` | Fetch linked Evolla history rows | [Get Evolla Linked History](/workflows/getEvollaLinkedHistory) |
| `PATCH` | `/v1/workflows/evolla/{workflow_id}/draft-question` | Update initial question for DRAFT Evolla workflow | [Update Evolla Draft Question](/workflows/updateEvollaDraftQuestion) |
| `GET` | `/v1/workflows/openmm/input-from-fold-job/preview` | Preview resolved OpenMM fold inputs | [Preview OpenMM Input From Fold Job](/workflows/previewOpenMMInputFromFoldJob) |
## Common call sequences
### BoltzGen graph workflow
1. `POST /v1/workflows/graph/add`
2. `POST /v1/workflows/{workflow_id}/workflow.yml` (or compose in UI — see [BoltzGen composer: If / Else and CEL](/sdk/boltzgen#boltzgen-composer-cel))
3. `POST /v1/workflows/execute`
4. `GET /v1/workflows/status/{workflow_id}` (poll)
5. `GET /v1/workflows/task-results/{workflow_id}`
6. Optional: `GET /v1/workflows/logs/{workflow_id}`
### BoltzGen one-shot YAML flow
1. `POST /v1/workflows/graph/from-yaml`
2. Optional: set `execute: true` to queue immediately
3. `GET /v1/workflows/status/{workflow_id}` (poll)
4. `GET /v1/workflows/task-results/{workflow_id}`
### Evolla/OpenMM workflow
1. `POST /v1/workflows`
2. `POST /v1/workflows/execute` (when required by workflow type)
3. `GET /v1/workflows/status/{workflow_id}` (poll)
4. `GET /v1/workflows/task-results/{workflow_id}`
# Preview OpenMM Input From Fold Job
Preview resolved structure/PAE inputs from a fold job before launching calvados\_openmm\_v1.
# Set Workflow YAML
Replace the workflow graph from YAML input and sync the canonical workflow\.yml artifact. Reference files and library items in this YAML must be created and managed through the Library API.
# Update Evolla Draft Question
Update the initial question for an evolla\_v1 workflow in DRAFT state.
# Update Workflow Public
Toggle public visibility for a workflow run. When public, the workflow can be fetched through the public endpoint.
# Data and Reports
Use data commands to prepare local datasets, and report commands to publish or share session outputs.
```bash
fastfold data list # catalog: description, size, auto/manual
fastfold data status # what's downloaded locally
fastfold data pull depmap # a single dataset
fastfold data pull-all # every auto-downloadable dataset (depmap is ~580MB)
fastfold config set data.depmap /path/to/depmap/ # point to existing data
```
`fastfold setup` also offers an optional dataset step with a multi-select (all
auto-downloadable datasets preselected). Non-interactive:
```bash
fastfold setup --datasets depmap,msigdb # specific datasets
fastfold setup --datasets all # everything auto-downloadable
fastfold setup --skip-datasets # skip the step
```
```bash
/data list # catalog of datasets
/data status # local download status
/data pull msigdb # download one dataset
/data pull-all # download everything auto-downloadable
```
```bash
fastfold report list
fastfold report publish
fastfold report show
```
```bash
/export-share
```
## Related pages
* Tool domain overview: [Tool categories](/agents/cli/tool-categories)
* Resume and session persistence: [Sessions and persistence](/agents/cli/sessions)
# Quick Start
## Install
Choose the install path that matches your environment.
Use these options when you want platform-specific setup or Docker install/run.
Requires **Python 3.11+**.
Install `uv` first using the official docs:
[Astral uv installation guide](https://docs.astral.sh/uv/getting-started/installation/).
```bash
uv tool install "fastfold-agent-cli[all]" --python 3.11
```
```bash
uv tool install "fastfold-agent-cli[win_build]" --python 3.11
```
If install fails on Windows, use **WSL2 + Ubuntu** for the smoothest experience.
```bash
# Install image
docker pull fastfold/fastfold-agent-cli:latest
# Run
docker run --rm -it fastfold/fastfold-agent-cli:latest
# Pin a specific release:
docker run --rm -it fastfold/fastfold-agent-cli:0.0.57
```
Fastfold Agent CLI (`fastfold`) is an agentic research environment for drug discovery and computational biology. Think of it as a coding agent, but for biology.
You ask questions in natural language, and it plans and executes multi-step workflows with built-in tools, skills, and cloud integrations.
Our mission is to bring the best tools to scientists wherever they work: on the cloud, on local compute, university HPC, or inside the enterprise.
Under the hood it runs on a [Deep Agents](https://docs.langchain.com/oss/python/deepagents/overview) (LangChain / LangGraph) agentic loop with **Programmatic Tool Calling (PTC)** and progressive skill discovery.
Many of its tools and prompts trace back to [CellType](https://github.com/celltype/celltype-agent), which reports a state-of-the-art **90% on BixBench-Verified-50**; see [Acknowledgements](#acknowledgements) for credits.
## Why Fastfold Agent CLI
* **190+ domain tools** across target discovery, chemistry, expression, viability, safety, and structure workflows.
* **Installable skills** to discover and run reusable workflows (`fastfold skills find`, `fastfold skills add ...`).
* **Any model setup** including Anthropic, OpenAI, and local/open models through OpenAI-compatible backends (like Ollama, Unsloth, oMLX, DS4, llama.cpp, and LM Studio).
* **Compute flexibility** for heavy workflows like folding, protein design, and MD across Fastfold Cloud or your own infrastructure.
* **Efficient agent runtime** built on Deep Agents (LangGraph) with progressive skill discovery and Programmatic Tool Calling, so large skill/tool catalogs stay fast and token-light.
* **PyPI:** [`fastfold-agent-cli`](https://pypi.org/project/fastfold-agent-cli/)
* **GitHub:** [fastfold-ai/fastfold-agent-cli](https://github.com/fastfold-ai/fastfold-agent-cli)
## Upgrading the Fastfold Agent CLI
Keep your CLI updated to get new tools and fixes.
```bash
/upgrade
```
```bash
uv tool install "fastfold-agent-cli[all]" --python 3.11 --upgrade
```
```bash
uv tool install "fastfold-agent-cli[win_build]" --python 3.11 --upgrade
```
Check your installed version:
```bash
fastfold --version
```
## Command guides
This CLI section is split into child pages so each command area is easier to scan:
* [Setup and local models](/agents/cli/setup) (`fastfold setup`, provider config, and compatible profile templates)
* [Usage and quick start](/agents/cli/usage) (`fastfold`, single prompts, `fastfold doctor`, `fastfold agent fork`, resume)
* [Interactive commands](/agents/cli/interactive-commands) (`/help`, `/model`, `/model-manager`, `/tasks`, `/upgrade`, and more)
* [Skills commands](/agents/cli/skills) (`fastfold skills ...` and `/skills...`)
* [Data and reports](/agents/cli/data-reports) (`fastfold data ...`, `fastfold report ...`, `/export-share`)
* [Tool categories](/agents/cli/tool-categories) (domain map of available tools)
* [Sessions and persistence](/agents/cli/sessions) (resume/history files and commands)
* [Troubleshooting](/agents/cli/troubleshooting) (common errors and fixes)
## Recommended first steps
If you are setting up for the first time, follow this order:
1. Install from this page.
2. Configure keys and provider in [Setup and local models](/agents/cli/setup).
3. Run your first query in [Usage and quick start](/agents/cli/usage).
## Benchmarks
**Coming soon.** We're crafting a comprehensive benchmark focused on industry-specific drug-discovery and computational-biology use cases: the multi-step, tool-heavy workflows scientists actually run, measured across multiple model backends. We're looking for contributors: if you have a real-world use case you'd like represented, or want to add tasks, datasets, or scoring rubrics, [open an issue](https://github.com/fastfold-ai/fastfold-agent-cli/issues) or reach out on Slack.
# Interactive Commands
Inside `fastfold` interactive mode, these slash commands control tools, sessions, models, exports, and background tasks.
| Command | Description |
| ----------------------- | ------------------------------------------------------------------------------------------- |
| `/help` | Command reference and examples |
| `/tools` | List tools |
| `/data` | Manage local datasets (`/data list`, `/data status`, `/data pull `, `/data pull-all`) |
| `/skills` | List installed skills (with author, last updated, and version) |
| `/skills-find [query]` | Search skill catalog |
| `/skills-add ` | Install a skill |
| `/skills-upgrade` | Sync the catalog and update installed skills |
| `/skills-remove ` | Remove a skill |
| `/model` | Switch model/provider from configured options |
| `/model-manager` | Add/edit/delete OpenAI-compatible profiles and inspect health/model discovery |
| `/settings` | UI + agent settings |
| `/keys` | Key status and key setup helpers (`/keys set-compatible `, `/keys set-boltz`) |
| `/new` | Start a new session |
| `/tasks` | Background task status |
| `/interrupt` | Stop active generation |
| `/agents N ` | Run N parallel research agents |
| `/sessions`, `/resume` | Session history + resume |
| `/export`, `/notebook` | Export output |
| `/upgrade` | Upgrade CLI |
| `/usage` | Token/cost usage |
## Common flows
Use these sequences for day-to-day work:
```bash
/model-manager
/model
/new
/tasks
/export
```
```bash
/skills-find fold
/skills-add fastfold-ai/skills@skills/fold
```
```bash
/keys
/keys set-boltz
```
## Related pages
* Install and upgrade: [Agent CLI Overview](/agents/cli)
* Setup and local model config: [Setup and local models](/agents/cli/setup)
* Session storage and resume options: [Sessions and persistence](/agents/cli/sessions)
# Sessions and Persistence
Agent CLI stores local config and session data so you can continue work across runs.
## Resume commands
Use these commands to continue previous sessions:
```bash
/sessions
/resume
/new
fastfold --resume
fastfold --continue
fastfold agent fork
```
## Local paths
Useful paths:
* config: `~/.fastfold-cli/config.json` (backup: `~/.fastfold-cli/config.json.bak`)
* interactive prompt history: `~/.fastfold-cli/history`
* sessions: `~/.fastfold-cli/sessions/.jsonl`
* trace events: `~/.fastfold-cli/sessions/.trace.jsonl`
* imported shared files: `/shared_forks//...`
## Fork shared cloud sessions
`fastfold agent fork ` imports a shared cloud thread into your local session storage.
Notes:
* You can pass either a share ID or a full `.../agents/share/` URL.
* Public-link shares can be imported without API key auth.
* Restricted-email shares require `FASTFOLD_API_KEY` for an allowed account.
* Use `--no-files` to import transcript only and skip file download.
## Related pages
* Setup and provider config: [Setup and local models](/agents/cli/setup)
* Interactive slash commands: [Interactive commands](/agents/cli/interactive-commands)
# Setup and Local Models
Use this page after installation to configure API keys, provider defaults, and OpenAI-compatible profile records.
## Setup wizard
The setup wizard is the recommended path for most users.
```bash
fastfold setup
```
```bash
export ANTHROPIC_API_KEY="sk-ant-..."
export OPENAI_API_KEY="sk-..."
export FASTFOLD_API_KEY="sk-..."
export BOLTZ_API_KEY="sk_bc_..."
```
```bash
fastfold setup --provider anthropic --api-key sk-ant-... --fastfold-api-key sk-...
fastfold setup --provider openai --openai-api-key sk-... --fastfold-api-key sk-...
fastfold setup --provider anthropic --api-key sk-ant-... --fastfold-api-key sk-... --boltz-api-key sk_bc_...
fastfold setup --provider openai_compatible --profile-label "oMLX Local" --profile-template omlx --profile-endpoint http://localhost:8000/v1 --profile-key sk-...
fastfold setup --provider openai_compatible --profile-label "DS4 Local" --profile-template ds4 --profile-endpoint http://localhost:8000/v1 --profile-key dsv4-local
fastfold setup --provider openai_compatible --profile-label "llama.cpp Local" --profile-template llama_cpp --profile-endpoint http://localhost:8080/v1
fastfold setup --provider openai_compatible --profile-label "LM Studio Local" --profile-template lm_studio --profile-endpoint http://localhost:1234/v1
# Skills and datasets non-interactively
fastfold setup --provider anthropic --api-key sk-ant-... --skills "fastfold-ai/skills@skills/fold" --datasets depmap,msigdb
fastfold setup --provider anthropic --api-key sk-ant-... --skip-skills --skip-datasets
```
## Optional setup steps
After keys, the wizard offers two optional steps (skip with flags for CI):
* **Skills** — multi-select from the live catalog. Non-interactive: `--skills ""` or `--skip-skills`.
* **Datasets** — multi-select of auto-downloadable datasets, all preselected. Non-interactive: `--datasets depmap,msigdb`, `--datasets all`, or `--skip-datasets`. See [Data and reports](/agents/cli/data-reports).
* **Boltz stack** (when `BOLTZ_API_KEY` is configured) — offers Boltz skill install plus `boltz-api` CLI install, then validates in `doctor` output.
## Provider configuration
Use these commands when you want explicit provider/model settings in config.
```bash
fastfold config set llm.provider anthropic
fastfold config set llm.model claude-sonnet-4-5-20250929
fastfold config set llm.anthropic_api_key sk-ant-...
```
```bash
fastfold config set llm.provider openai
fastfold config set llm.model gpt-5.5
fastfold config set llm.openai_api_key sk-...
```
```bash
fastfold setup --provider openai_compatible \
--profile-label "Ollama Local" \
--profile-template ollama \
--profile-endpoint http://localhost:11434/v1 \
--profile-key ollama
```
## Provider integrations (`/keys`)
Use `/keys` (interactive) or `fastfold keys` (shell) to inspect provider status and config key mappings.
| Service | Env var | Config key | Unlocks | Get key / setup |
| ----------------- | --------------------------- | --------------------------------------------- | --------------------------------------------- | ---------------------------------------------------------------------------------- |
| Anthropic | `ANTHROPIC_API_KEY` | `llm.anthropic_api_key` | Claude model access | [console.anthropic.com/settings/keys](https://console.anthropic.com/settings/keys) |
| OpenAI | `OPENAI_API_KEY` | `llm.openai_api_key` | OpenAI model access | [platform.openai.com/api-keys](https://platform.openai.com/api-keys) |
| OpenAI-compatible | `OPENAI_COMPATIBLE_API_KEY` | `llm.openai_compatible_api_key` / profile key | Local/self-hosted OpenAI-compatible endpoints | [Ollama API docs](https://docs.ollama.com/api/introduction) |
| Fastfold AI Cloud | `FASTFOLD_API_KEY` | `api.fastfold_cloud_key` | Fastfold cloud skills and integrations | [cloud.fastfold.ai/api-keys](https://cloud.fastfold.ai/api-keys) |
| Boltz | `BOLTZ_API_KEY` | `api.boltz_api_key` | Boltz API skills | [api.boltz.bio/console](https://api.boltz.bio/console) |
| IBM RXN | `IBM_RXN_API_KEY` | `api.ibm_rxn_key` | Retrosynthesis workflows | [rxn.res.ibm.com](https://rxn.res.ibm.com) |
| Lens.org | `LENS_API_KEY` | `api.lens_key` | Patent search workflows | [lens.org subscriptions](https://www.lens.org/lens/user/subscriptions) |
| SendGrid | `SENDGRID_API_KEY` | `notification.sendgrid_api_key` | Email notification delivery | [sendgrid.com](https://sendgrid.com) |
| Lambda Labs | `LAMBDA_API_KEY` | `compute.lambda_api_key` | GPU compute jobs | [cloud.lambdalabs.com](https://cloud.lambdalabs.com) |
| RunPod | `RUNPOD_API_KEY` | `compute.runpod_api_key` | GPU compute jobs | [runpod.io](https://www.runpod.io) |
Boltz quick setup inside interactive mode:
```bash
/keys set-boltz
```
Configured tool keys are mirrored into the session environment on startup, so shell/skill subprocesses can read `BOLTZ_API_KEY` and `FASTFOLD_API_KEY` without extra export commands.
## Local and OpenAI-compatible models
Use this for Ollama, Unsloth, oMLX, DS4, llama.cpp, LM Studio, or another OpenAI-compatible endpoint.
Profiles are the system of record for compatible providers.
Start with the wizard:
```bash
fastfold setup --provider openai_compatible
```
The wizard asks for backend type, base URL, API key, and available model.
It now also shows a summary (profile/template/endpoint) before model selection.
Typical defaults:
* Ollama: `http://localhost:11434/v1`
* Unsloth: `http://localhost:8888/v1`
* oMLX: `http://localhost:8000/v1`
* DS4: `http://localhost:8000/v1`
* llama.cpp: `http://localhost:8080/v1`
* LM Studio: `http://localhost:1234/v1`
Template values:
* `ollama`
* `unsloth`
* `omlx`
* `ds4`
* `llama_cpp`
* `lm_studio`
* `other`
Useful profile flags for scripted setup:
```bash
fastfold setup --provider openai_compatible \
--profile-label "Custom Gateway" \
--profile-template other \
--profile-endpoint https://gateway.example.com/v1 \
--profile-key sk-... \
--profile-default-model gpt-oss-120b \
--set-default-profile
```
Interactive workflow:
* `/model` selects from configured models/providers (selection only).
* `/model-manager` adds/edits/deletes compatible profiles and shows endpoint health + discovered models.
* `/keys set-compatible ` updates a specific compatible profile key.
* `/keys set-boltz` updates `BOLTZ_API_KEY` and offers Boltz skill + CLI installation.
When a local compatible backend is active (for example Ollama) but a cloud-only model id remains selected (`gpt-*`), the CLI auto-heals to the active profile default model to prevent 404 model-not-found loops.
If `/model-manager` shows `no models` for Unsloth, auth is usually valid but no model is loaded in Unsloth Studio yet.
## Inference engine install references
Before creating compatible profiles in Fastfold, install/run one of these local inference engines:
* **DS4 (DeepSeek v4 Flash/PRO):** [antirez/ds4](https://github.com/antirez/ds4)
* **llama.cpp:** [ggml-org/llama.cpp](https://github.com/ggml-org/llama.cpp)
* **LM Studio (OpenAI-compatible server):** [OpenAI Compatibility Endpoints](https://lmstudio.ai/docs/developer/openai-compat)
* **Ollama:** [ollama/ollama](https://github.com/ollama/ollama)
* **oMLX:** [jundot/omlx](https://github.com/jundot/omlx)
* **Unsloth:** [unslothai/unsloth](https://github.com/unslothai/unsloth)
## Related pages
* Install and upgrade overview: [Agent CLI Overview](/agents/cli)
* First query and health checks: [Usage and quick start](/agents/cli/usage)
* Interactive commands: [Interactive commands](/agents/cli/interactive-commands)
# Skills Commands
Skills are reusable workflows (folding, MD, design, reporting) that the Agent CLI can run on demand.
The CLI ships helper skills, and domain skills are installed from the [Fastfold catalog](https://github.com/fastfold-ai/skills).
## Manage skills from shell
```bash
fastfold skills list
fastfold skills find [query]
```
```bash
fastfold skills add fastfold-ai/skills@skills/fold
fastfold skills add fastfold-ai/skills
```
```bash
fastfold skills upgrade
fastfold skills remove fold
```
## Manage skills from interactive mode
```bash
/skills
/skills-find [query]
/skills-add
/skills-upgrade
/skills-remove
```
`fastfold setup` and `/upgrade` can also offer to install missing Fastfold skills automatically.
## Versioning and updates
The Fastfold catalog is versioned with GitHub Releases (one semver tag per catalog version). The CLI uses that release to show versions and to notify you when a newer catalog is available.
* **See versions:** `fastfold skills list` (and `/skills`) show **Author**, **Updated**, and **Version** columns. The version is the catalog's latest release tag (for example `v1.0.0`); the author is the source repo's org (for example `fastfold-ai`). Skills installed from a source without a release — such as npx-installed or bundled helper skills — show `Version not available`.
* **Upgrade:** run `fastfold skills upgrade` (or `/skills-upgrade`) to sync the catalog, update installed skills, and record the latest release version.
On launch, the CLI shows a non-blocking notice when a newer catalog release exists:
```text
Skills update available: v1.0.0 -> v1.1.0 Run /skills-upgrade
```
The check reads a local cache (no network on startup) and refreshes in the background, so it never slows boot. The notice appears on the next launch after a new release is published.
## Related pages
* General setup and provider config: [Setup and local models](/agents/cli/setup)
* Data/report commands commonly used with skills: [Data and reports](/agents/cli/data-reports)
* Full skills ecosystem guide: [Skills](/agents/skills)
# Tool Categories
The Agent CLI includes 190+ tools grouped by scientific domain.
| Category | Examples |
| -------------- | -------------------------------------------------------------------------------------------- |
| **Target** | Neosubstrate scoring, degron prediction, co-essentiality networks |
| **Chemistry** | SAR analysis, fingerprint similarity, scaffold clustering |
| **Expression** | L1000 signatures, pathway enrichment, TF activity, immune scoring |
| **Viability** | Dose-response modeling, PRISM screening, therapeutic windows |
| **Structure** | AlphaFold fetch, docking, binding sites, MD simulation |
| **Folding** | Fastfold AI Cloud: boltz-2, openfold3, chai1, intellifold, monomer, multimer, simplefold\_\* |
| **Literature** | PubMed, OpenAlex, ChEMBL search |
| **DNA** | ORF finding, codon optimization, primer design |
Inspect your current environment:
```bash
fastfold tool list
fastfold skills list
```
## Related pages
* Running prompts and health checks: [Usage and quick start](/agents/cli/usage)
* Skills command guide: [Skills commands](/agents/cli/skills)
# Troubleshooting
If something fails, start with these common checks.
| Symptom | Fix |
| ----------------------------------------- | ----------------------------------------------------------------------------------------------- |
| `fastfold` fails at startup | `fastfold doctor` |
| Authentication failed (401 / invalid key) | Set a valid key: `fastfold config set llm.anthropic_api_key sk-ant-...` or run `fastfold setup` |
| Data not found | Check `fastfold data status`, then `fastfold data pull ` (or `fastfold data pull-all`) |
| Windows dependency issues | Use WSL2 + Ubuntu, or install `[win_build]` |
| Missing dependency | Reinstall with `uv tool install "fastfold-agent-cli[all]" --python 3.11` |
| Resume last session | `fastfold --continue` |
## Diagnostic commands
```bash
fastfold doctor
fastfold --version
fastfold setup
```
## Related pages
* Install and upgrade commands: [Agent CLI Overview](/agents/cli)
* Setup and provider config: [Setup and local models](/agents/cli/setup)
# Usage and Quick Start
These commands are the fastest way to verify your install and start real workflows.
## Quick start commands
```bash
fastfold
```
```bash
fastfold "Top degradation targets for this compound?"
```
```bash
fastfold doctor
```
```bash
fastfold --continue
```
```bash
fastfold agent fork
```
## Example prompts
Use natural-language prompts like these for common research workflows.
```bash
fastfold "I have a CRBN glue. Which degron target should I prioritize?"
```
```bash
fastfold "Fold this sequence with boltz-2 and find binding pockets: MALWMRLLPLL..."
```
```bash
fastfold "My lead is immune-cold. What combination strategy should I test?"
```
## Continue from here
* Slash command reference: [Interactive commands](/agents/cli/interactive-commands)
* Provider and local model setup: [Setup and local models](/agents/cli/setup)
* Sessions and persistence details: [Sessions and persistence](/agents/cli/sessions)
# BoltzGen
Use BoltzGen to run `boltzgen_v1` graph workflows.
fastfold/boltzgen
— image tag is chosen by the deployment (examples in API specs may show
fastfold/boltzgen:v0.2.0
or
fastfold/boltzgen:latest
)
## Metrics and Artifacts
### Task results (`GET /v1/workflows/task-results/`)
For **`task_type == pipeline_run_boltzgen_v1`**, when a **`final_designs_metrics_*.csv`** is present among outputs, **`parsed_results`** lists one object per design row (subset of CSV columns). Rows can include a **`file`** object with `libraryItemId` and `fileName` for the ranked **CIF** when filenames match the `rank{n}_*.cif` pattern.
Allowed keys in **`parsed_results`** mirror the metrics CSV, for example: `id`, `final_rank`, `designed_sequence`, `num_design`, `design_ptm`, `design_hydrophobicity`, `loop`, `helix`, `sheet`, `ligand_iptm`, `interaction_pae`, `min_interaction_pae`, `iptm`, `ptm`, `design_iiptm`, `target_ptm`, `max_rank`, `secondary_rank`, `quality_score`, and `bindsite_under_3rmsd` through `bindsite_under_9rmsd`.
All tasks also return **`output_library_items`** with library-backed artifacts (CSVs, PDF, CIF, etc.).
### Declared keys (`output-schema`)
Call **`POST /v1/workflows/node/output-schema`** with **`workflowTaskTypeId: pipeline_run_boltzgen_v1`**. The body must include **`inputPayload.numDesigns`** and may include **`budget`** (top‑K ranks). The response lists **`availableOutput[]`** for composer validation.
**Metric-like names** use **`designs[<0-based index>].`** where the index equals **`final_rank - 1`** in the exported CSV.
| Suffix | Declared type | Description |
| ----------------------------------------------- | ------------- | --------------------- |
| `ptm` | key/float | PTM score |
| `design_ptm` | key/float | Design PTM score |
| `design_hydrophobicity` | key/float | Design hydrophobicity |
| `loop` | key/float | Loop score |
| `ligand_iptm` | key/float | Ligand IPTM |
| `final_rank` | key/integer | Final rank |
| `secondary_rank` | key/integer | Secondary rank |
| `helix` | key/float | Helix score |
| `iptm` | key/float | IPTM score |
| `interaction_pae` | key/float | Interaction PAE |
| `bindsite_under_3rmsd` … `bindsite_under_9rmsd` | key/float | Bindsite RMSD bands |
| `num_design` | key/integer | Design index |
| `designed_sequence` | key/string | Designed sequence |
| `min_interaction_pae` | key/float | Min interaction PAE |
| `design_iiptm` | key/float | Design ipTM |
| `target_ptm` | key/float | Target PTM |
| `sheet` | key/float | Sheet score |
| `max_rank` | key/integer | Max rank |
| `quality_score` | key/float | Quality score |
**Declared files** (types such as `file/CSV`):
| Name pattern | Description |
| ------------------------------------ | ------------------------------------------------------------ |
| `all_designs_metrics.csv` | All designs metrics |
| `results_overview.pdf` | Overview PDF |
| `final_designs_metrics_.csv` | Top‑K metrics CSV used for branching |
| `rank{n}_*.cif` | Ranked structures (filename padding depends on `numDesigns`) |
### SDK and CLI
Use the same patterns as in [Logs and results](#logs-and-results) below: `client.workflows.task_results(workflow_id)` or:
```bash
fastfold-cli workflows task-results
fastfold-cli workflows task-results --json
```
## Composer: If / Else and CEL
The **BoltzGen composer** (UI: `/workflow/composer/...`) builds a `boltzgen_v1` graph: Design Spec → BoltzGen pipeline → optional **If / Else** → branches → **End** nodes.
### If / Else node
* **Placement:** An If / Else node must follow a step with an **output schema**. The enforced predecessor for branching is **BoltzGen** (`pipeline_run_boltzgen_v1`): **Design Spec → BoltzGen**, then **BoltzGen → If / Else**.
* **Branches:** Two outgoing handles — **`true`** and **`false`**. At most **one** downstream node per handle.
* **YAML:** Branching is stored under top-level **`conditions`**: each entry has `source`, `target`, and **`sourceHandle`** (`"true"` or `"false"`; YAML booleans are normalized on ingest).
```yaml
conditions:
- source: if_else
target: run_followup
sourceHandle: true
- source: if_else
target: end_early
sourceHandle: false
```
The expression string is **`inputPayload.expressionCEL`** on the If / Else job.
### Common Expression Language (CEL)
**CEL** expresses **boolean** conditions over workflow outputs. The composer validates names against the **Declared keys** list above (via `output-schema`).
**Evaluation context (BoltzGen → If / Else):** the worker reads **`final_designs_metrics_*.csv`**, builds a context like:
```json
{
"designs": [
{ "ptm": 0.83, "iptm": 0.71, "final_rank": 1, "designed_sequence": "..." }
]
}
```
Index **`designs[0]`** matches **`final_rank == 1`**. Field names align with **`designs[i].`** from `output-schema` for `pipeline_run_boltzgen_v1`.
**Examples (CEL):**
```text
designs[0].iptm >= 0.7
```
```text
designs[0].ptm > 0.8 && designs[0].interaction_pae < 12.0
```
```text
designs[0].quality_score != null && designs[0].quality_score > 0.5
```
```text
size(designs[0].designed_sequence) > 100
```
Reference: [cel.dev](https://cel.dev).
The If / Else task **must** have a non-empty **`expressionCEL`** or the worker errors when executing that task.
**Scope:** `output-schema` also lists **OpenMM / OpenMMDL** metric paths for UIs. **Graph If / Else execution** evaluates CEL on **BoltzGen CSV metrics** when the immediate predecessor is **`pipeline_run_boltzgen_v1`**.
### Discovering variables in the UI
1. Select **If / Else** after **BoltzGen**.
2. Open the condition editor — keys match `output-schema` (metrics as `designs[i].…`, files as `file/…` types).
3. Use **How to** in the panel for CEL examples.
## Input schemas
BoltzGen workflows involve two nested inputs:
* the outer API request body used to create or update the workflow
* the inner `workflow.yml` graph spec, including the design-spec YAML referenced by that graph
The one-shot create-from-YAML body is:
```json
{
"workflow_name": "boltzgen_v1",
"workflow_yml": "version: 1\njobs:\n ...",
"name": "boltzgen_from_yml",
"create_mode": "",
"execute": true
}
```
The packaged sample uses the following `workflow.yml` shape:
```yaml
version: 1
jobs:
start:
type: start
position:
x: 66.67
y: 133.33
description: Workflow start point
label: Start
design_spec:
type: input
subType: design_specification_yml
workflowTaskTypeId: input_design_spec_boltzgen_v1
position:
x: 327.78
y: 133.33
inputPayload:
inputYML: design_spec.example.yaml
inputYMLLibraryItemId: 11111111-1111-1111-1111-111111111111
files:
- libraryItemId: 22222222-2222-2222-2222-222222222222
fileName: 5cqg.cif
label: Design Spec
boltzgen:
type: pipeline
subType: boltzgen
workflowTaskTypeId: pipeline_run_boltzgen_v1
position:
x: 588.89
y: 133.33
inputPayload:
protocolName: protein-anything
numDesigns: 1
budget: 1
label: BoltzGen
end:
type: end
position:
x: 850
y: 133.33
description: Workflow end point
label: End
workflows:
main:
jobs:
- start
- design_spec:
requires: [start]
- boltzgen:
requires: [design_spec]
- end:
requires: [boltzgen]
```
The following design-spec YAML is referenced by `inputPayload.inputYML`:
```yaml
entities:
- protein:
id: G
sequence: 12..20
- file:
path: 5cqg.cif
include:
- chain:
id: A
binding_types:
- chain:
id: A
binding: 343,344,251
structure_groups: "all"
```
Field notes:
* `workflow_yml` is required for the one-shot create endpoint.
* `jobs..position.x` and `.y` are optional editor coordinates, not semantic run settings.
* The design-spec input node must reference a real uploaded design-spec YAML via `inputYMLLibraryItemId`.
* `inputPayload.files[].libraryItemId` and `fileName` must point to real uploaded structure files referenced by the design-spec YAML.
* `protocolName`, `numDesigns`, and `budget` are the core packaged pipeline fields for the sample graph.
## Downloadable Preset Files
This section includes the current non-empty BoltzGen example presets so you can download the exact files and run them locally with the SDK or CLI. Keep the original filenames when saving these files locally, because many specs reference neighboring files by name.
Note: BoltzGen presets are not all shaped the same way. Some presets contain a single self-contained design-spec file, while others compose multiple referenced YAML specs and structure files into one run.
### 1. Vanilla Peptide
* Design-spec YAML: [`vanilla_target_binding_site.design_spec.yaml`](/examples/boltzgen/presets/vanilla_target_binding_site.design_spec.yaml)
* Target structure: [`5cqg.cif`](/examples/boltzgen/boltzgen_templates/5cqg.cif)
### 2. Vanilla Protein
* Design-spec YAML: [`vanilla_protein.design_spec.yaml`](/examples/boltzgen/presets/vanilla_protein.design_spec.yaml)
* Target structure: [`1g13.cif`](/examples/boltzgen/boltzgen_templates/1g13.cif)
### 3. Binding Disordered Peptides
* Design-spec YAML: [`binding_disordered_peptides.design_spec.yaml`](/examples/boltzgen/presets/binding_disordered_peptides.design_spec.yaml)
* This starter preset does not require an uploaded target structure file.
### 4. Protein Binding Small Molecule
* Design-spec YAML: [`protein_binding_small_molecule.design_spec.yaml`](/examples/boltzgen/presets/protein_binding_small_molecule.design_spec.yaml)
* This starter preset does not require an uploaded target structure file.
* The ligand is encoded directly in the spec as CCD `TSA`.
### 5. Small Molecule From File And Smiles
* Design-spec YAML: [`small_molecule_from_file_and_smiles.design_spec.yaml`](/examples/boltzgen/presets/small_molecule_from_file_and_smiles.design_spec.yaml)
* Structure file: [`4g37.pdb`](/examples/boltzgen/boltzgen_templates/4g37.pdb)
### 6. Cyclic Against HIV Antibody Site
* Design-spec YAML: [`9d3d.yaml`](/examples/boltzgen/boltzgen_templates/9d3d.yaml)
* Target structure: [`9d3d.cif`](/examples/boltzgen/boltzgen_templates/9d3d.cif)
### 7. Nanobody Against Penguinpox (Multi-Spec)
* Main design-spec YAML: [`penguinpox.yaml`](/examples/boltzgen/boltzgen_templates/nanobody_against_penguinpox/penguinpox.yaml)
* Main target structure: [`9bkq-assembly2.cif`](/examples/boltzgen/boltzgen_templates/nanobody_against_penguinpox/9bkq-assembly2.cif)
* Scaffold 1: [`7eow.yaml`](/examples/boltzgen/boltzgen_templates/nanobody_scaffolds/7eow.yaml) and [`7eow.cif`](/examples/boltzgen/boltzgen_templates/nanobody_scaffolds/7eow.cif)
* Scaffold 2: [`7xl0.yaml`](/examples/boltzgen/boltzgen_templates/nanobody_scaffolds/7xl0.yaml) and [`7xl0.cif`](/examples/boltzgen/boltzgen_templates/nanobody_scaffolds/7xl0.cif)
* Scaffold 3: [`gontivimab.yaml`](/examples/boltzgen/boltzgen_templates/nanobody_scaffolds/gontivimab.yaml) and [`gontivimab.cif`](/examples/boltzgen/boltzgen_templates/nanobody_scaffolds/gontivimab.cif)
* Scaffold 4: [`isecarosmab.yaml`](/examples/boltzgen/boltzgen_templates/nanobody_scaffolds/isecarosmab.yaml) and [`isecarosmab.cif`](/examples/boltzgen/boltzgen_templates/nanobody_scaffolds/isecarosmab.cif)
* Scaffold 5: [`sonelokimab.yaml`](/examples/boltzgen/boltzgen_templates/nanobody_scaffolds/sonelokimab.yaml) and [`sonelokimab.cif`](/examples/boltzgen/boltzgen_templates/nanobody_scaffolds/sonelokimab.cif)
This preset uses referenced specs. In the workflow composer, each referenced YAML or structure file is uploaded as its own library item, and the main design-spec YAML references those uploaded files by basename:
```yaml
entities:
- file:
path: 9bkq-assembly2.cif
include:
- chain:
id: B
- file:
path: 7eow.yaml
- file:
path: 7xl0.yaml
- file:
path: gontivimab.yaml
- file:
path: isecarosmab.yaml
- file:
path: sonelokimab.yaml
```
The composer also persists library references alongside that YAML. For a multi-spec node, the effective node payload follows this pattern:
```json
{
"inputYML": "penguinpox.yaml",
"inputYMLLibraryItemId": "",
"files": [
{ "libraryItemId": "", "fileName": "9bkq-assembly2.cif" },
{ "libraryItemId": "", "fileName": "7eow.yaml" },
{ "libraryItemId": "", "fileName": "7eow.cif" },
{ "libraryItemId": "", "fileName": "7xl0.yaml" },
{ "libraryItemId": "", "fileName": "7xl0.cif" }
]
}
```
Note: The YAML itself does not carry library item IDs. Resolution happens through the design-spec node payload: `inputYML` and `inputYMLLibraryItemId` identify the main YAML file, and `files[]` provides the uploaded file mapping for every referenced YAML or structure file.
Tip: In practice, use the uploaded file basename in `path` values such as `7eow.yaml` or `9bkq-assembly2.cif`. The backend can fall back to basename matching, but matching `files[].fileName` directly is the safest published pattern.
Reminder: Referenced scaffold YAML files can themselves point to additional structure files. Upload the full file set, not only the top-level `penguinpox.yaml`.
For the multi-spec preset, preserve the folder layout when downloading locally:
* `nanobody_against_penguinpox/penguinpox.yaml`
* `nanobody_against_penguinpox/9bkq-assembly2.cif`
* `nanobody_scaffolds/*.yaml`
* `nanobody_scaffolds/*.cif`
The `empty` preset is intentionally not listed here because it does not ship example input files.
## Create a draft
```python
from fastfold import Client
client = Client()
draft = client.boltzgen.create_draft(name="boltzgen_demo")
print(draft.workflow_id)
```
```bash
fastfold-cli workflows boltzgen create-draft --name boltzgen_demo
```
## Build a minimal `workflow.yml`
The SDK package ships lightweight example assets:
* `fastfold/examples/boltzgen/design_spec.example.yaml`
* `fastfold/examples/boltzgen/minimal.workflow.yml`
* `fastfold/examples/boltzgen/replacements.example.json`
The packaged example uses the graph-spec shape expected by the workflow YAML endpoints:
* `jobs.` entries define node type, subtype, task type, labels, and `inputPayload`
* `workflows.main.jobs` defines execution order and `requires`
* `input_design_spec_boltzgen_v1` needs a design-spec YAML file plus referenced uploaded structure files
`position.x` and `position.y` are editor coordinates. Keep them if you want the graph to open nicely in Composer, but they are not the semantic part of the run configuration.
Tip: Start from the packaged minimal graph when you want a clean draft that is easy to reason about. Move to the larger preset bundles only after you are comfortable with the file-linking pattern.
```bash
fastfold-cli workflows boltzgen build-spec \
--template-file fastfold/examples/boltzgen/minimal.workflow.yml \
--replacements-file fastfold/examples/boltzgen/replacements.example.json \
--output ./workflow.yml
```
Required files for the packaged sample after replacement:
* a design-spec YAML such as `fastfold/examples/boltzgen/design_spec.example.yaml`
* at least one uploaded structure file such as `5cqg.cif`
* matching library item IDs for those uploaded files
Note: `workflow.yml` stores references to uploaded library items, not local filesystem paths. Upload the inputs first, then substitute the resulting library item IDs into the workflow spec.
For additional presets and domain-specific reference bundles, see the published examples in `fastfold-skills`.
## Design-spec example to upload first
The packaged design-spec example uses the following structure:
```yaml
entities:
- protein:
id: G
sequence: 12..20
- file:
path: 5cqg.cif
include:
- chain:
id: A
binding_types:
- chain:
id: A
binding: 343,344,251
structure_groups: "all"
```
Upload the design-spec YAML and the referenced structure file to the library first, then link those uploaded items from the workflow YAML.
Reminder: The `path` field inside the design-spec YAML still needs to match the referenced filename. If the uploaded structure file is named `5cqg.cif`, keep `path: 5cqg.cif` in the YAML.
```python
from fastfold import Client
client = Client()
design_spec_ref = client.boltzgen.upload_input(
file_path="fastfold/examples/boltzgen/design_spec.example.yaml",
file_type="yml",
item_name="beetletert",
)
structure_ref = client.boltzgen.upload_input(
file_path="./5cqg.cif",
file_type="protein",
item_name="5cqg",
)
print(design_spec_ref.library_item_id, structure_ref.library_item_id)
```
Those uploaded IDs are what you place into `inputYMLLibraryItemId` and `files[].libraryItemId` in the workflow YAML.
Tip: Keep a small mapping file of local filename to library item ID while preparing a workflow. It makes replacement into `workflow.yml` much less error-prone for multi-file examples.
## Upload or replace `workflow.yml`
```python
from pathlib import Path
from fastfold import Client
client = Client()
workflow_id = "af2473ef-820d-44df-98fe-fa15103157d5"
client.boltzgen.upsert_workflow_yml(workflow_id, Path("./workflow.yml").read_text())
print(client.boltzgen.get_workflow_yml(workflow_id))
```
```bash
fastfold-cli workflows boltzgen set-yml af2473ef-820d-44df-98fe-fa15103157d5 --file ./workflow.yml
fastfold-cli workflows boltzgen get-yml af2473ef-820d-44df-98fe-fa15103157d5
```
## One-shot create from `workflow.yml`
```python
from pathlib import Path
from fastfold import Client
client = Client()
workflow = client.boltzgen.create_from_workflow_yml(
Path("./workflow.yml").read_text(),
name="boltzgen_from_yml",
execute=True,
)
print(workflow.workflow_id)
```
```bash
fastfold-cli workflows boltzgen create-from-yml --file ./workflow.yml --name boltzgen_from_yml --execute
```
## Logs and results
```python
from fastfold import Client
client = Client()
workflow_id = "af2473ef-820d-44df-98fe-fa15103157d5"
print(client.boltzgen.get_logs(workflow_id))
print(client.workflows.task_results(workflow_id).raw)
```
Related API docs:
* [/workflows/addWorkflowGraph](/workflows/addWorkflowGraph)
* [/workflows/getWorkflowYml](/workflows/getWorkflowYml)
* [/workflows/setWorkflowYml](/workflows/setWorkflowYml)
* [/workflows/executeWorkflow](/workflows/executeWorkflow)
# Evolla
Use Evolla to run `evolla_v1` workflows — a single **`inference_evolla`** task answers a natural-language **`question`** about a structure, using the configured Evolla model inside the worker image.
fastfold/evolla
— default
fastfold/evolla:latest
(configurable per deployment)
## Submit a run (SDK and CLI)
**Python** — **local structure file** (uploads to your library, then runs with `targetSource: upload`, same as the web UI):
```python
wf = client.evolla.submit_from_local_file(
"./structure.cif",
"What structural features stand out in this fold?",
name="Evolla upload demo",
)
print(wf.workflow_id)
```
**Python** — from a **completed** fold job (infers job run id and default protein sequence; resolves `sourceUserId` from the signed CIF path when possible):
```python
from fastfold import Client
client = Client()
wf = client.evolla.submit_from_fold_job(
"YOUR_JOB_ID",
"What is the function of this protein?",
)
print(wf.workflow_id)
```
If job results expose a CIF URL whose path is **not** `/{userId}/{jobRunId}/{sequenceId}/model.cif`, pass `source_user_id="YOUR_UUID"` or set **`FASTFOLD_EVOLLA_SOURCE_USER_ID`** (or **`FASTFOLD_SOURCE_USER_ID`**).
**Python** — arbitrary `workflow_input` (upload, PDB, UniProt, library, or full `sequence` payload), same as the API:
```python
wf = client.evolla.submit(
{
"targetSource": "pdb",
"pdbId": "1ABC",
"question": "What structural class is this?",
},
name="Evolla PDB demo",
)
```
**CLI**
```bash
fastfold-cli workflows evolla from-file ./structure.cif --question "What is the function of this protein?"
fastfold-cli workflows evolla from-fold-job YOUR_JOB_ID --question "What is the function of this protein?"
fastfold-cli workflows evolla from-input --file ./workflow_input.json --name "Evolla from file"
```
Packaged template: `fastfold/examples/evolla/from_fold_job.template.json` (replace placeholders). For the REST shape, see [Create Workflow Run](/workflows/createWorkflowRun).
## Metrics and Artifacts
Evolla does **not** use the shared **`POST /v1/workflows/node/output-schema`** catalog for `inference_evolla` today (that endpoint is used for BoltzGen composer fields and OpenMM-class MD metrics). Read answers from **`result_raw_json`** on each completed task instead.
### Task results (`GET /v1/workflows/task-results/`)
In **`tasksResults[]`**, rows with **`task_type`** **`inference_evolla`** expose:
| Field | Meaning |
| ----------------------------------- | ---------------------------------------------------------------------- |
| **`result_raw_json.question`** | Prompt sent to the model |
| **`result_raw_json.answer`** | Parsed model reply (plain text) |
| **`result_raw_json.targetSource`** | How the structure was resolved (for example fold job vs manual upload) |
| **`result_raw_json.targetRef`** | Reference id(s) tying the run back to your fold job or library item |
| **`result_raw_json.fileName`** | Local CIF filename used inside the worker |
| **`result_raw_json.image`** | Container image that ran the task (audit/debug) |
| **`result_raw_json.job_yaml_path`** | Worker-side path to generated metadata (audit/debug) |
**`output_library_items`** is typically **empty** for Evolla; the primary artifact is the structured JSON above. Long-form logs may also be linked from the workflow record when the deployment uploads them.
### Reading task results
```python
from fastfold import Client
client = Client()
out = client.workflows.task_results(workflow_id)
print(out.raw)
```
```bash
fastfold-cli workflows task-results
fastfold-cli workflows task-results --json
```
### Linked workflows and drafts
When Evolla is launched from a fold result, the API can list other workflows for the same job/run and update a draft question before execute:
* **`GET /v1/workflows/evolla/linked-history`** — history keyed by `source_job_id`, `source_job_run_id`, and `source_sequence_id` ([API ref](/workflows/getEvollaLinkedHistory))
* **`GET /v1/workflows/evolla/linked-previews`** — lightweight linked rows by job/run ([API ref](/workflows/getEvollaLinkedPreviews))
* **`PATCH /v1/workflows/evolla//draft-question`** — set `question` on a **DRAFT** workflow ([API ref](/workflows/updateEvollaDraftQuestion))
Python (`client.workflows`):
* `linked_history(source_job_id=..., source_job_run_id=..., source_sequence_id=..., limit=...)`
* `linked_previews(source_job_id=..., source_job_run_id=..., limit=...)`
* `update_evolla_draft_question(workflow_id, question)`
### See also
* [Create Workflow Run](/workflows/createWorkflowRun) — raw `workflow_name: evolla_v1` payloads
* [/workflows/getWorkflowTaskResults](/workflows/getWorkflowTaskResults)
# Fold
**Fold** is Fastfold’s **structure prediction** path: you submit sequences and, where the model allows, **additional chains**, ligands, nucleic acids, or constraints. The job returns **mmCIF/PDB**, **confidence metrics** (pLDDT, PAE, pTM/ipTM when emitted), and **plot URLs** you can use in a structure viewer or hand off to **workflows** (for example MD, protein design, or structure Q\&A). Each [model](#models) is backed by a published container on [Docker Hub](https://hub.docker.com/u/fastfold); **`POST /v1/jobs`** and **`GET /v1/jobs/{job_id}/results`** are the same whether you use this page’s Python examples, the [CLI](/sdk/cli), or raw HTTP.
Quick reference
API
Fold jobs —
POST /v1/jobs
,
GET /v1/jobs/{jobId}/results
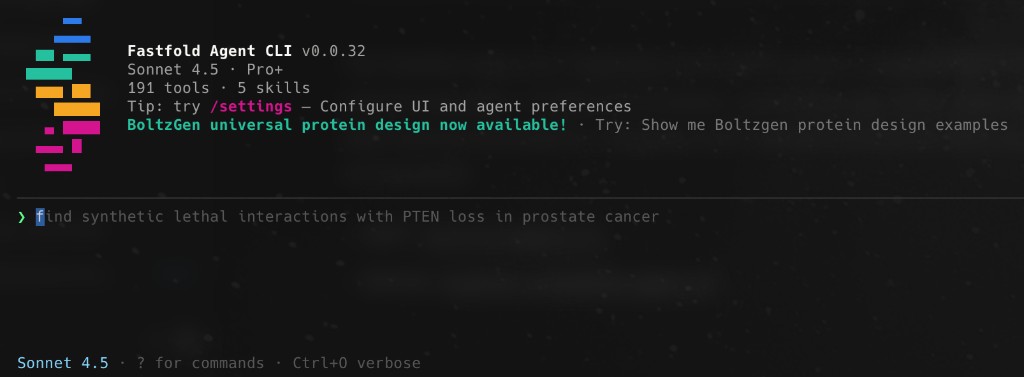
 */}
***
## Example queries
### Target prioritization
```bash
fastfold "I have a CRBN molecular glue. Proteomics shows it degrades IKZF1, GSPT1,
and CK1α. Which target should I prioritize?"
```
### Protein folding
```bash
fastfold "Fold this sequence with boltz-2 and find the binding pockets: MALWMRLLPLL..."
```
{/* Screenshot: protein folding result with structure viewer link */}
{/*
 */}
### Combination strategy
```bash
fastfold "My lead compound is immune-cold. What combination strategy should I use?"
```
***
## Interactive mode commands
Inside `fastfold` interactive mode:
| Command | Description |
| ----------------------- | -------------------------------------------------------------------------------------------------- |
| `/help` | Command reference and examples |
| `/tools` | List all tools with status |
| `/skills` | List currently loaded skills (author, last updated, version) |
| `/skills-find [query]` | Discover installable skills from the Fastfold catalog |
| `/skills-add
 */}
***
## Local sessions and persistence
Agent CLI persists interactive session history locally by default. You can close and reopen the CLI, then continue prior work with `/sessions`, `/resume`, `fastfold --resume
 */}
***
## Troubleshooting
| Symptom | Fix |
| ----------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `fastfold` fails at startup | `fastfold doctor` |
| No API key error | `fastfold setup` or `export ANTHROPIC_API_KEY=...` |
| Data not found | `fastfold data pull


 ## Agent CLI
Use Agent CLI when you want Fastfold to interpret prompts, choose tools, and execute multi-step workflows from one terminal session.
### Fast path (install -> setup -> first run)
```bash
uv tool install "fastfold-agent-cli[all]" --python 3.10
fastfold setup
fastfold "Fold this sequence with boltz-2 and show binding pockets: MALWMRLLPLL..."
```
### Everyday quick commands
```bash
fastfold # interactive mode
fastfold doctor # health checks
fastfold --continue # resume last session
```
### Agent CLI references
* Overview and install: [/agents/cli](/agents/cli)
* Setup and local models (Ollama/OpenAI-compatible): [/agents/cli/setup](/agents/cli/setup)
* Quick usage and prompt examples: [/agents/cli/usage](/agents/cli/usage)
* Interactive slash commands: [/agents/cli/interactive-commands](/agents/cli/interactive-commands)
* Skills commands: [/agents/cli/skills](/agents/cli/skills)
* Data/report commands: [/agents/cli/data-reports](/agents/cli/data-reports)
* Troubleshooting: [/agents/cli/troubleshooting](/agents/cli/troubleshooting)
If you want lower-level control for scripts, notebooks, or CI, continue with the SDK path below.
## Python SDK and CLI
If you prefer scriptable control and reproducible pipelines, use the SDK and SDK CLI path.
### Create an API key
Store the key in `FASTFOLD_API_KEY` so both the SDK and CLI pick it up automatically.